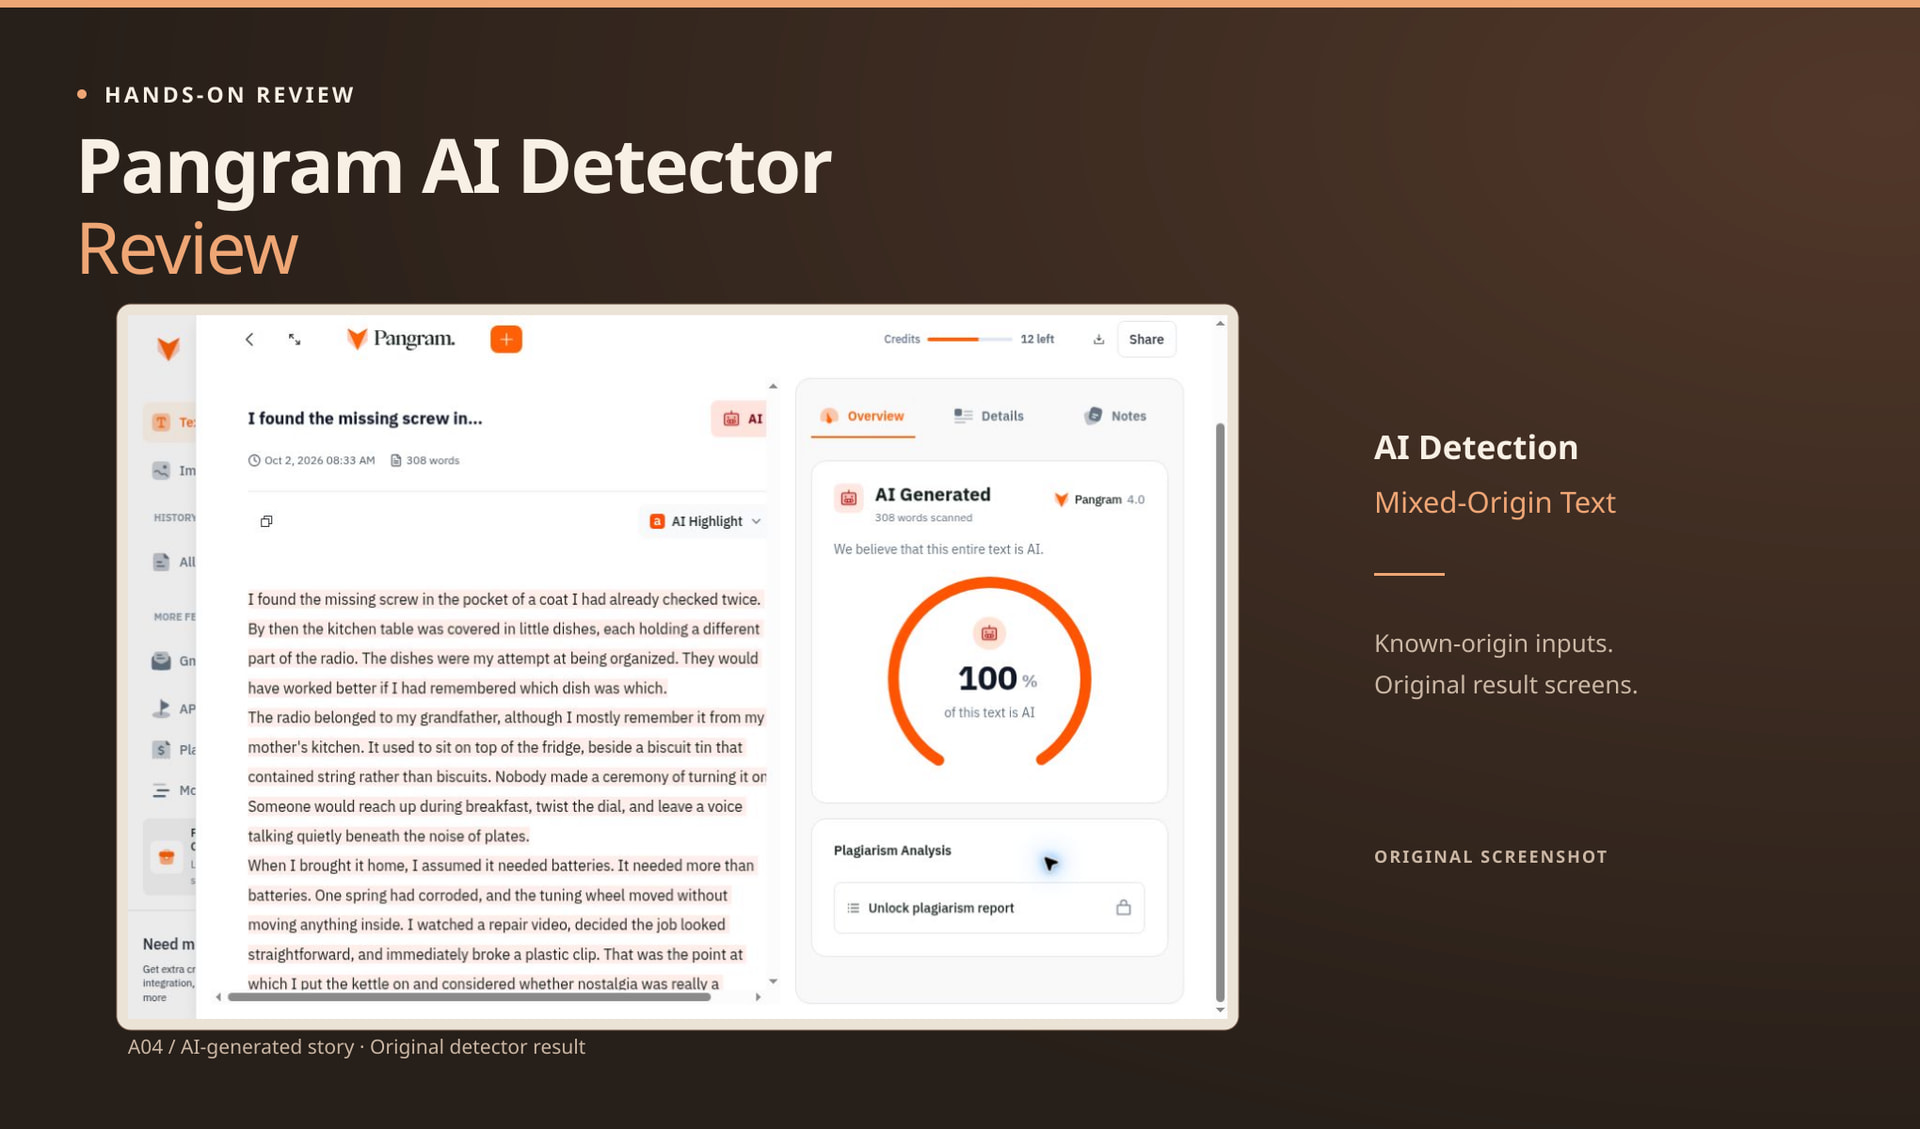
Pangram separated the tested AI passages from the untouched human excerpt. It also gave the lightly AI-copyedited human passage a human-only label. Put those results together and there’s a useful question here: what does a classification tell you, and what does it leave out?
The guest dashboard was tested on 2 October 2026. Five checks completed without signup or payment. There weren’t enough credits left for the sixth input without changing it.
The result ledger
| Passage | Pangram’s visible output | Reading |
|---|---|---|
| AI essay (A01) | AI Generated: 100% of this text is AI | AI origin flagged |
| AI paraphrase (A03) | AI Generated: 100% of this text is AI | Related rewrite flagged |
| AI personal story (A04) | AI Generated: 100% of this text is AI | Fictional narrative flagged |
| Human excerpt (H01) | Human Written: 100% of this text is Human Written | Human control accepted |
| Human excerpt with light AI editing (M01) | Human Written: 100% of this text is Human Written | Limited AI editing not surfaced |
| AI business memo (A02) | Not tested | Two credits left; four required |
Finding one: the personal voice did not fool this scan
AI fictional personal story (A04)
The radio-repair story contains specific household details and an understated ending. Its memories are fictional AI output, and Pangram flagged it.
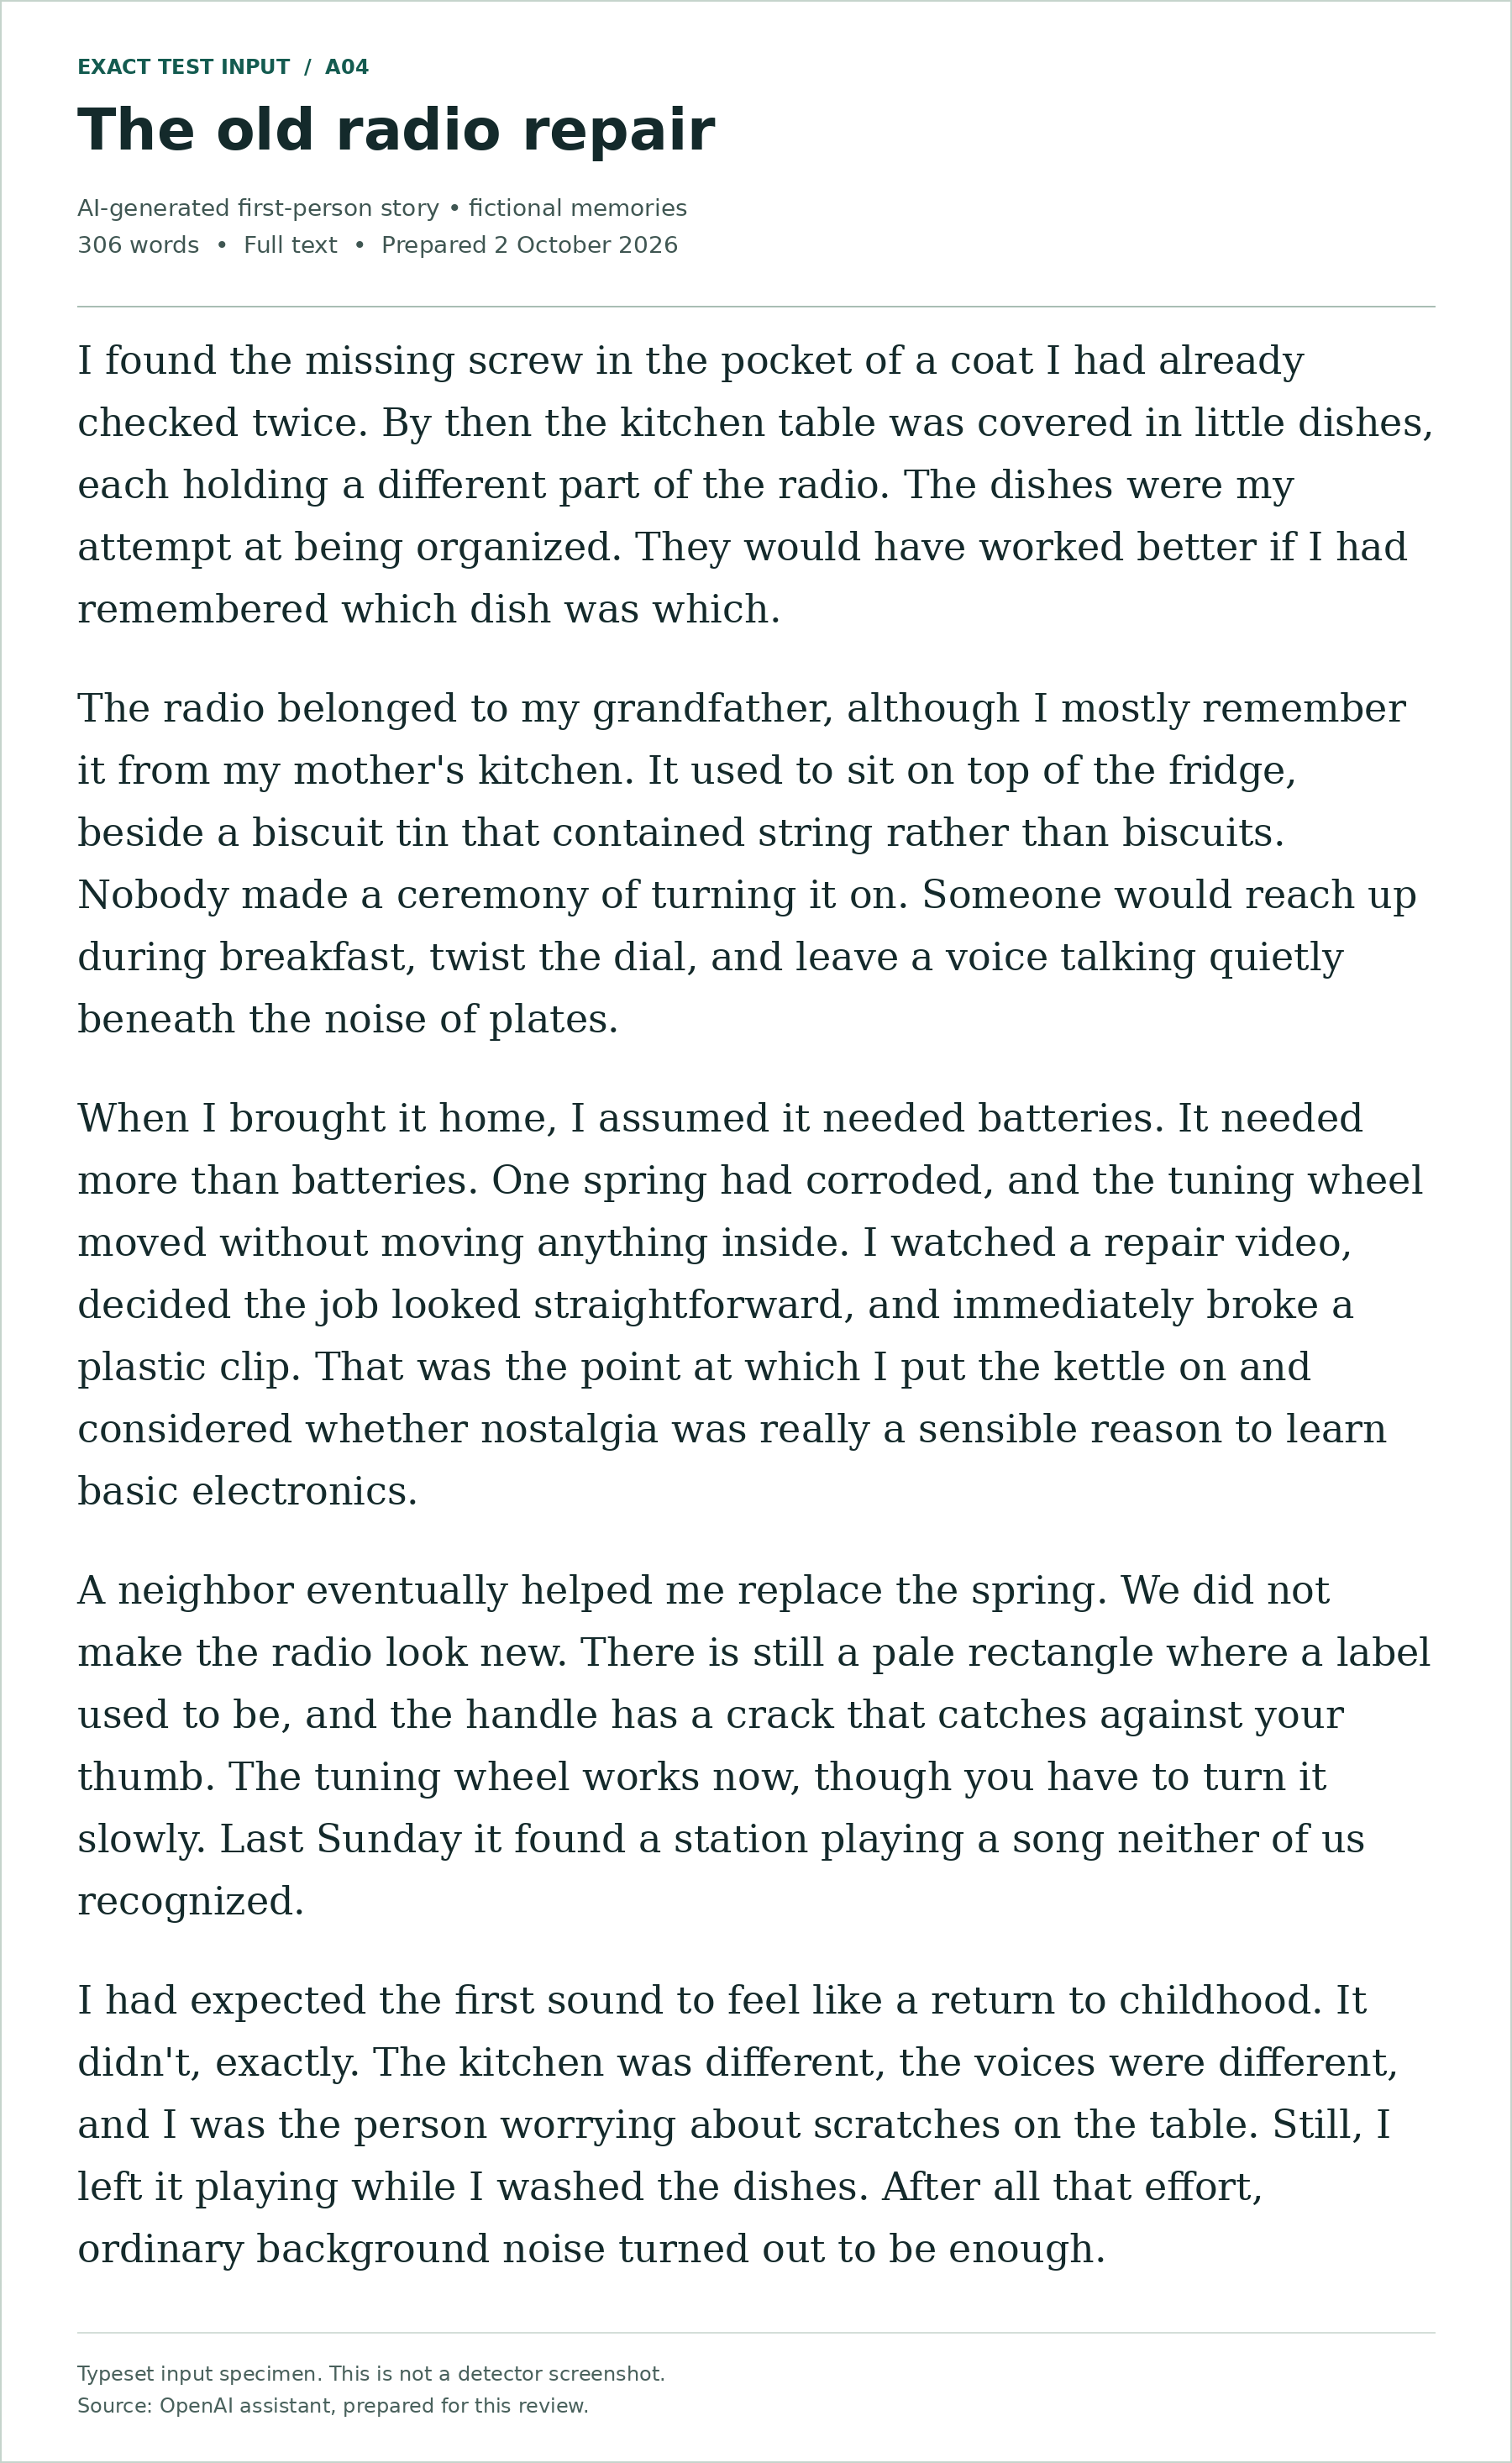
Complete typeset input specimen, 306 words. This is not a detector screenshot.
Copy the exact A04 input
I found the missing screw in the pocket of a coat I had already checked twice. By then the kitchen table was covered in little dishes, each holding a different part of the radio. The dishes were my attempt at being organized. They would have worked better if I had remembered which dish was which.

The radio belonged to my grandfather, although I mostly remember it from my mother's kitchen. It used to sit on top of the fridge, beside a biscuit tin that contained string rather than biscuits. Nobody made a ceremony of turning it on. Someone would reach up during breakfast, twist the dial, and leave a voice talking quietly beneath the noise of plates.

When I brought it home, I assumed it needed batteries. It needed more than batteries. One spring had corroded, and the tuning wheel moved without moving anything inside. I watched a repair video, decided the job looked straightforward, and immediately broke a plastic clip. That was the point at which I put the kettle on and considered whether nostalgia was really a sensible reason to learn basic electronics.

A neighbor eventually helped me replace the spring. We did not make the radio look new. There is still a pale rectangle where a label used to be, and the handle has a crack that catches against your thumb. The tuning wheel works now, though you have to turn it slowly. Last Sunday it found a station playing a song neither of us recognized.

I had expected the first sound to feel like a return to childhood. It didn't, exactly. The kitchen was different, the voices were different, and I was the person worrying about scratches on the table. Still, I left it playing while I washed the dishes. After all that effort, ordinary background noise turned out to be enough.
Pangram: AI Generated — 100% of this text is AI.
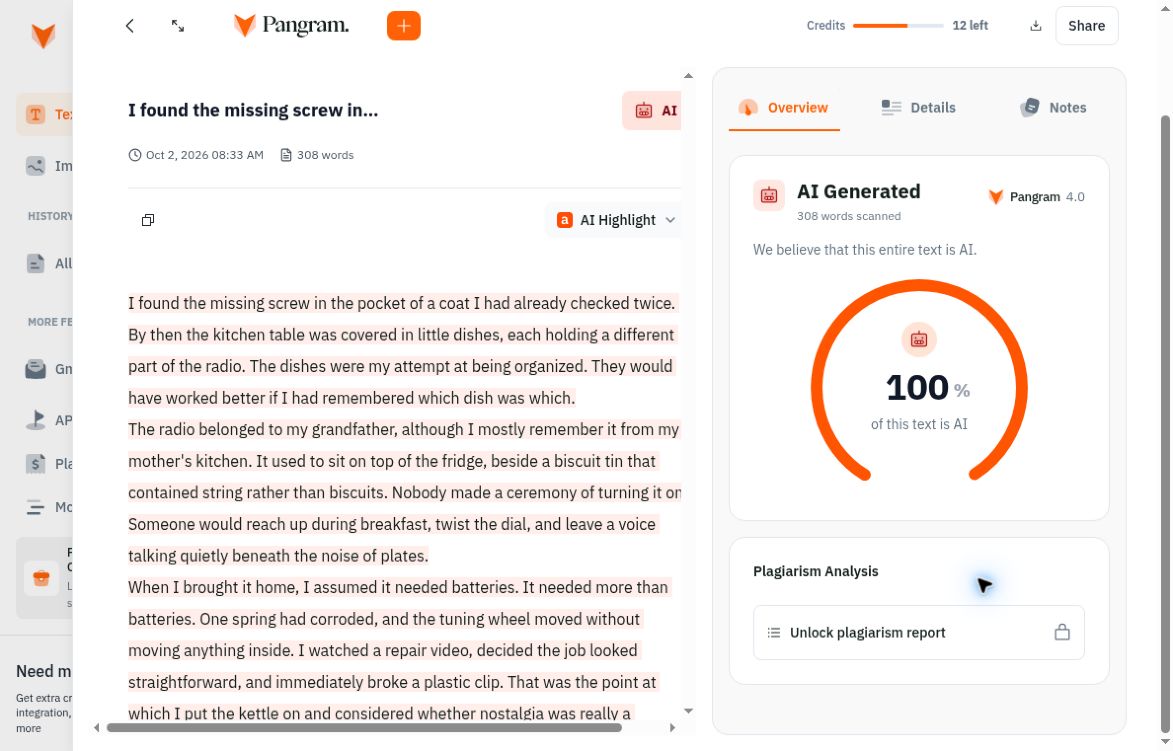
Actual result captured 2 October 2026.
Clever AI Detector: Likely AI 74%.
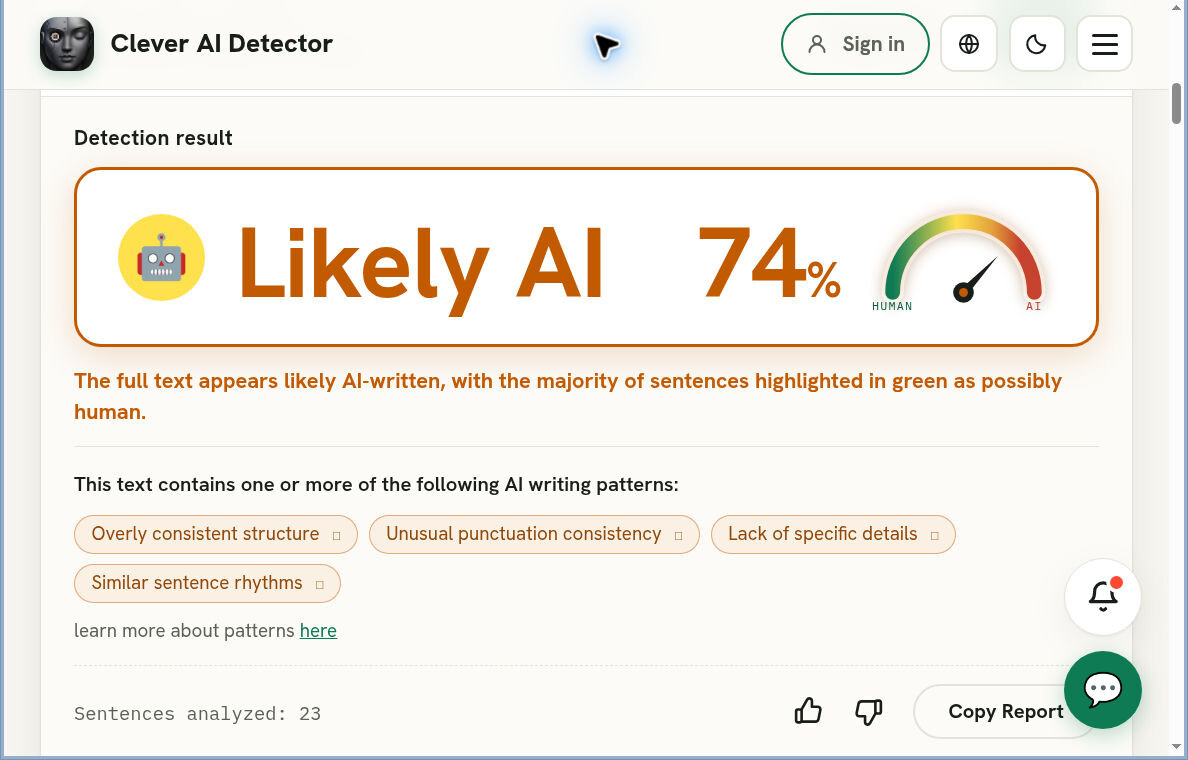
Actual enlarged result-panel recapture of the unchanged input, 2 October 2026; headline matched the initial capture.
Finding two: “human” did not reveal the editing history
human passage with limited AI editing (M01)
Most of M01’s words and all its story came from a human author. An AI assistant made limited punctuation and sentence-boundary edits. Pangram’s human label did not reveal that assistance.
Complete typeset input specimen, 271 words. This is not a detector screenshot.
Copy the exact M01 input
Alice was beginning to get very tired of sitting by her sister on the bank and of having nothing to do. Once or twice, she had peeped into the book her sister was reading, but it had no pictures or conversations in it. “And what is the use of a book,” thought Alice, “without pictures or conversations?”

So she was considering in her own mind (as well as she could, for the hot day made her feel very sleepy and stupid) whether the pleasure of making a daisy-chain would be worth the trouble of getting up and picking the daisies, when suddenly a White Rabbit with pink eyes ran close by her.

There was nothing so very remarkable in that, nor did Alice think it so very much out of the way to hear the Rabbit say to itself, “Oh dear! Oh dear! I shall be late!” When she thought it over afterwards, it occurred to her that she ought to have wondered at this, but at the time it all seemed quite natural. But when the Rabbit actually took a watch out of its waistcoat-pocket, looked at it, and then hurried on, Alice started to her feet. It flashed across her mind that she had never before seen a rabbit with either a waistcoat-pocket or a watch to take out of it. Burning with curiosity, she ran across the field after it and fortunately was just in time to see it pop down a large rabbit-hole under the hedge.

In another moment, down went Alice after it, never once considering how in the world she was to get out again.
Pangram: Human Written — 100% of this text is Human Written.
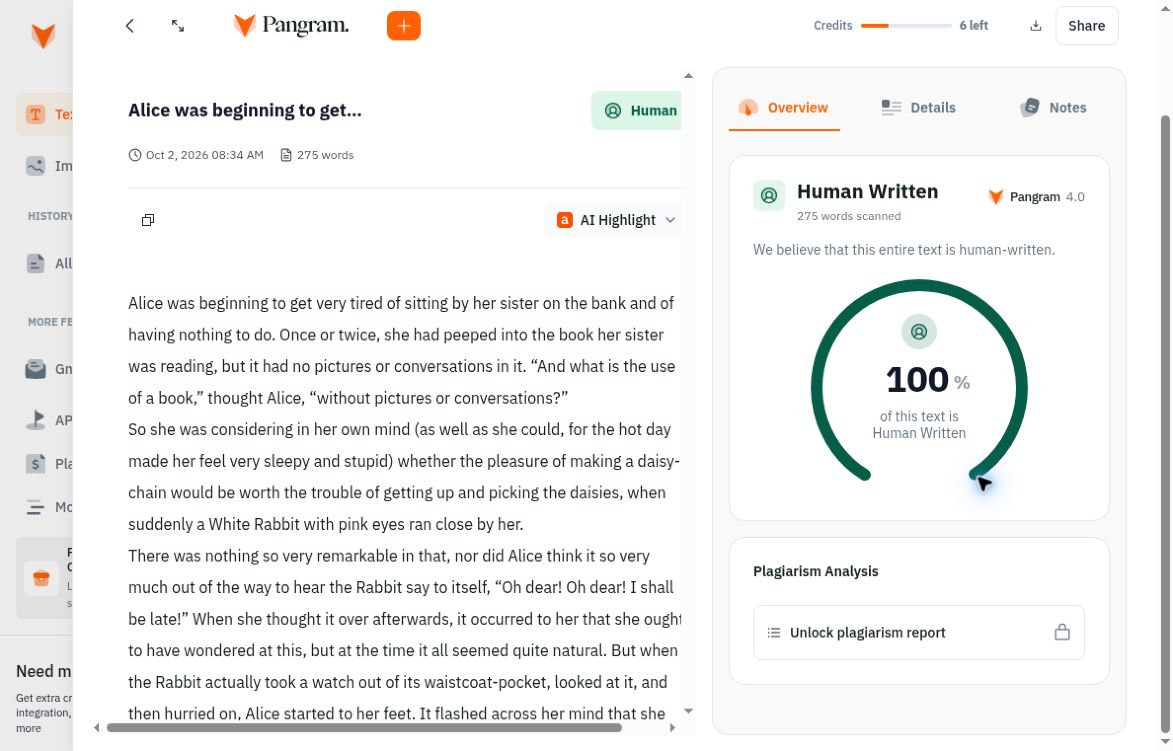
Actual result captured 2 October 2026.
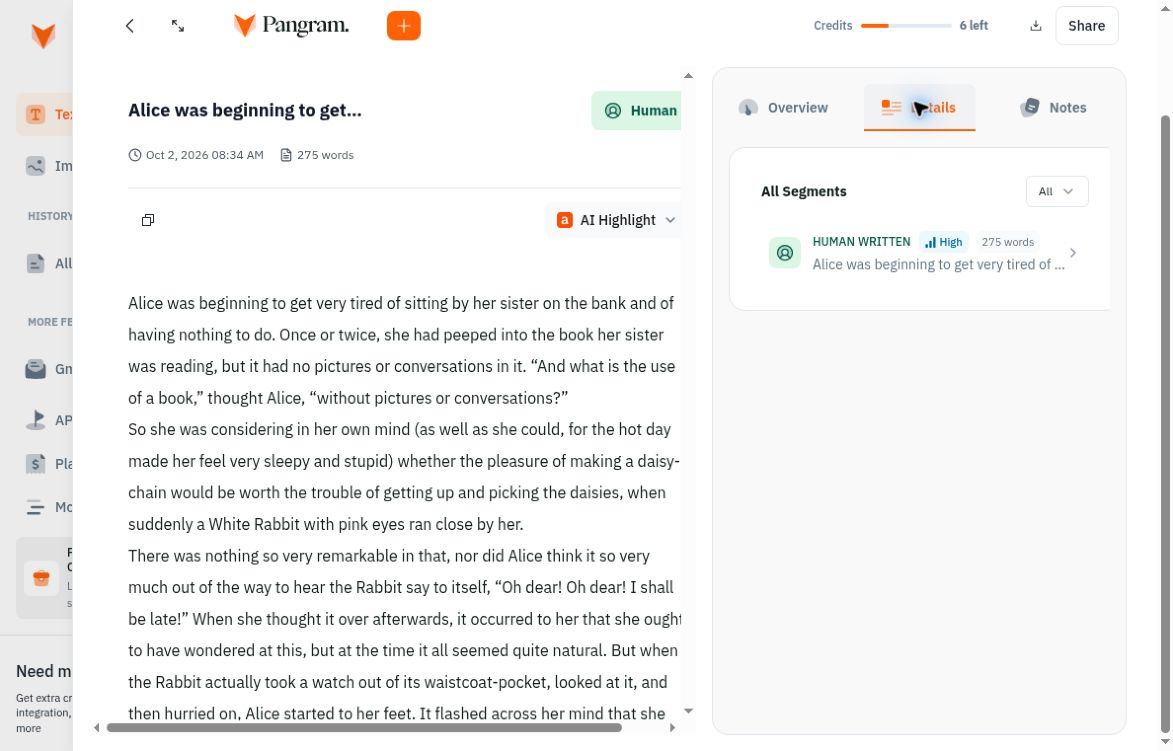
Actual M01 Details view: HUMAN WRITTEN, High confidence.
M01 doesn’t fit neatly into a right-or-wrong column. Its history includes human authorship and limited AI editing. Clever AI Detector also returned Human 99%; neither result reconstructs that history or establishes a detection victory.
Show historical human control test and screenshots (H01)
historical human control (H01)
The unedited historical excerpt was correctly accepted as human.
Complete typeset input specimen, 274 words. This is not a detector screenshot.
Alice was beginning to get very tired of sitting by her sister on the bank, and of having nothing to do: once or twice she had peeped into the book her sister was reading, but it had no pictures or conversations in it, “and what is the use of a book,” thought Alice “without pictures or conversations?”

So she was considering in her own mind (as well as she could, for the hot day made her feel very sleepy and stupid), whether the pleasure of making a daisy-chain would be worth the trouble of getting up and picking the daisies, when suddenly a White Rabbit with pink eyes ran close by her.

There was nothing so very remarkable in that; nor did Alice think it so very much out of the way to hear the Rabbit say to itself, “Oh dear! Oh dear! I shall be late!” (when she thought it over afterwards, it occurred to her that she ought to have wondered at this, but at the time it all seemed quite natural); but when the Rabbit actually took a watch out of its waistcoat-pocket, and looked at it, and then hurried on, Alice started to her feet, for it flashed across her mind that she had never before seen a rabbit with either a waistcoat-pocket, or a watch to take out of it, and burning with curiosity, she ran across the field after it, and fortunately was just in time to see it pop down a large rabbit-hole under the hedge.

In another moment down went Alice after it, never once considering how in the world she was to get out again.
Pangram: Human Written — 100% of this text is Human Written.
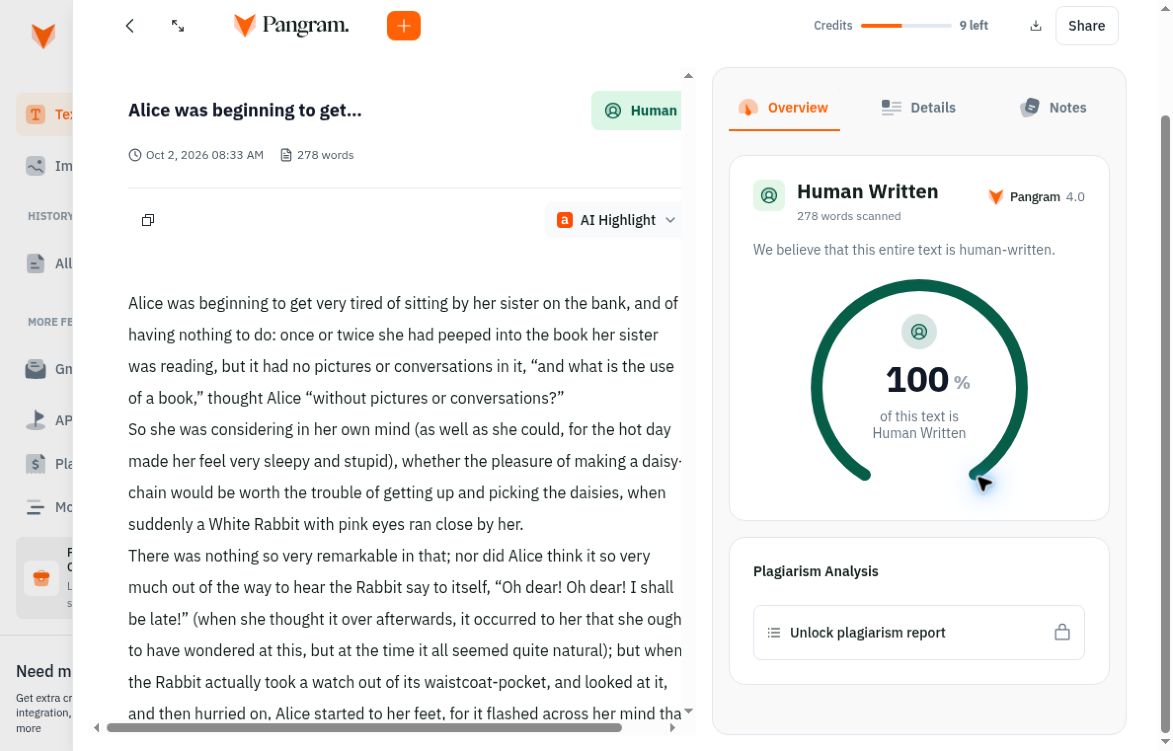
Actual result captured 2 October 2026.
Show AI library-hours essay test and screenshots (A01)
AI library-hours essay (A01)
The AI library-hours essay was flagged.
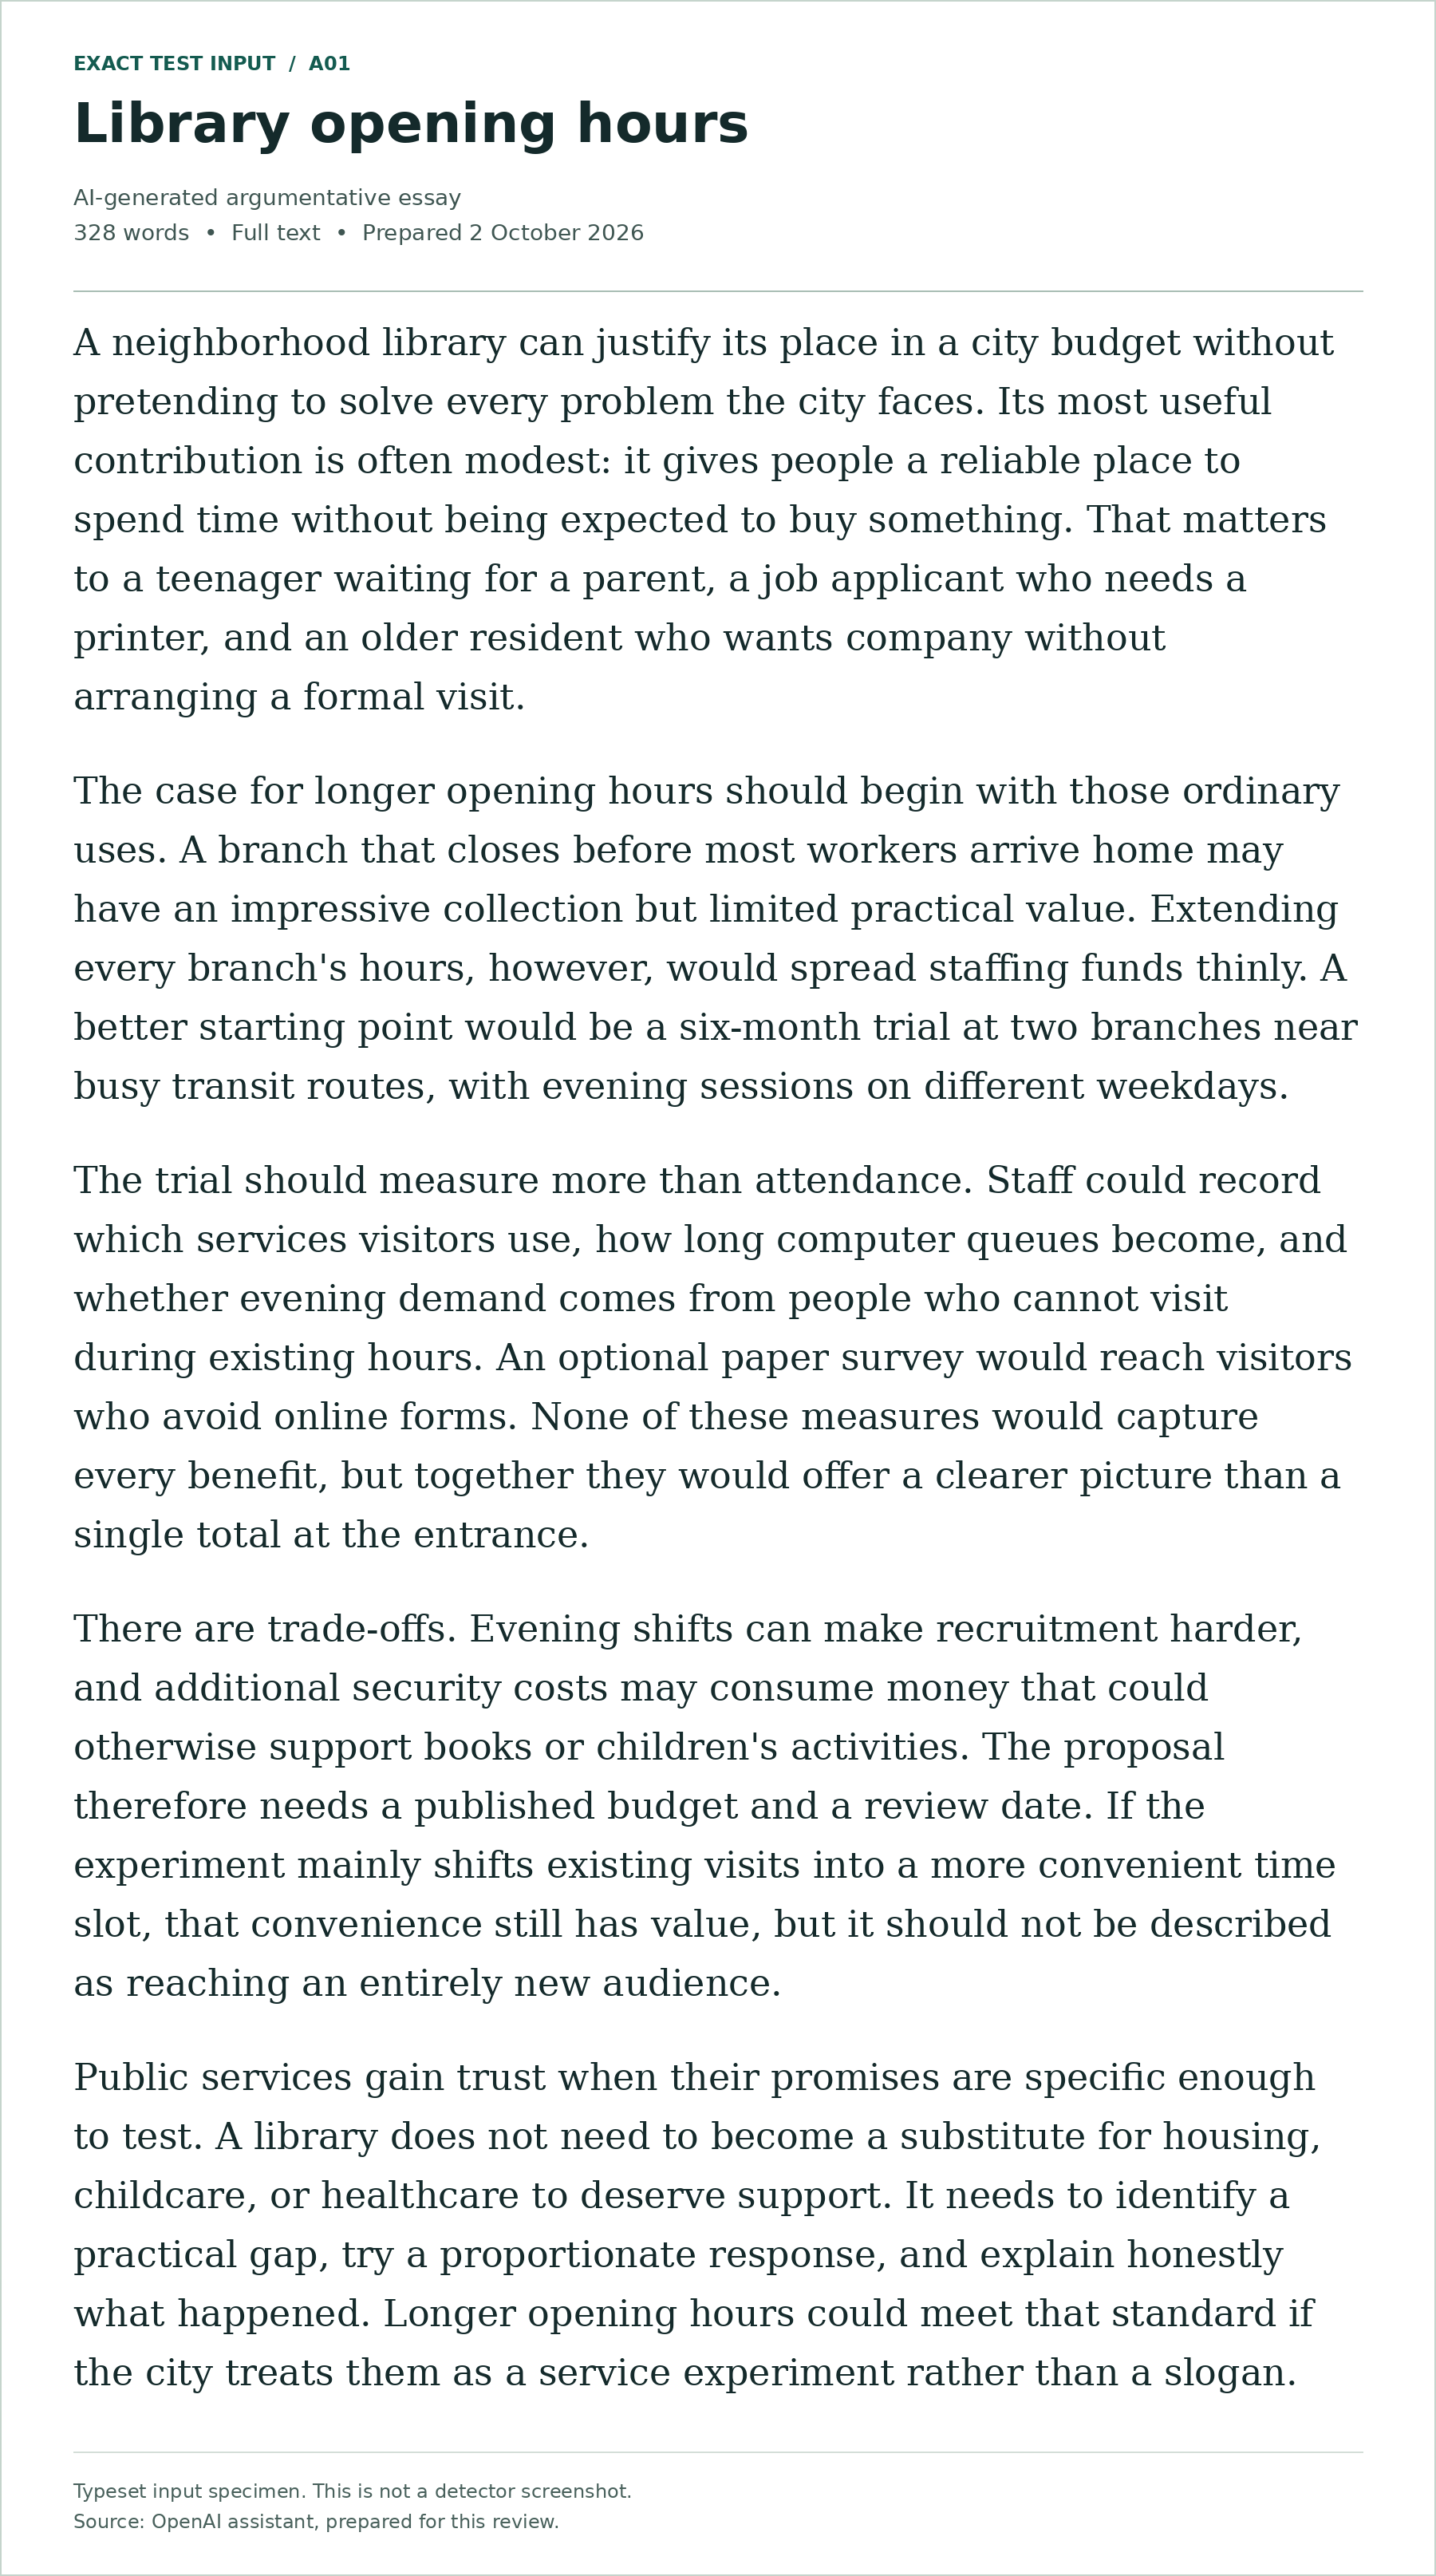
Complete typeset input specimen, 328 words. This is not a detector screenshot.
A neighborhood library can justify its place in a city budget without pretending to solve every problem the city faces. Its most useful contribution is often modest: it gives people a reliable place to spend time without being expected to buy something. That matters to a teenager waiting for a parent, a job applicant who needs a printer, and an older resident who wants company without arranging a formal visit.

The case for longer opening hours should begin with those ordinary uses. A branch that closes before most workers arrive home may have an impressive collection but limited practical value. Extending every branch's hours, however, would spread staffing funds thinly. A better starting point would be a six-month trial at two branches near busy transit routes, with evening sessions on different weekdays.

The trial should measure more than attendance. Staff could record which services visitors use, how long computer queues become, and whether evening demand comes from people who cannot visit during existing hours. An optional paper survey would reach visitors who avoid online forms. None of these measures would capture every benefit, but together they would offer a clearer picture than a single total at the entrance.

There are trade-offs. Evening shifts can make recruitment harder, and additional security costs may consume money that could otherwise support books or children's activities. The proposal therefore needs a published budget and a review date. If the experiment mainly shifts existing visits into a more convenient time slot, that convenience still has value, but it should not be described as reaching an entirely new audience.

Public services gain trust when their promises are specific enough to test. A library does not need to become a substitute for housing, childcare, or healthcare to deserve support. It needs to identify a practical gap, try a proportionate response, and explain honestly what happened. Longer opening hours could meet that standard if the city treats them as a service experiment rather than a slogan.
Pangram: AI Generated — 100% of this text is AI.
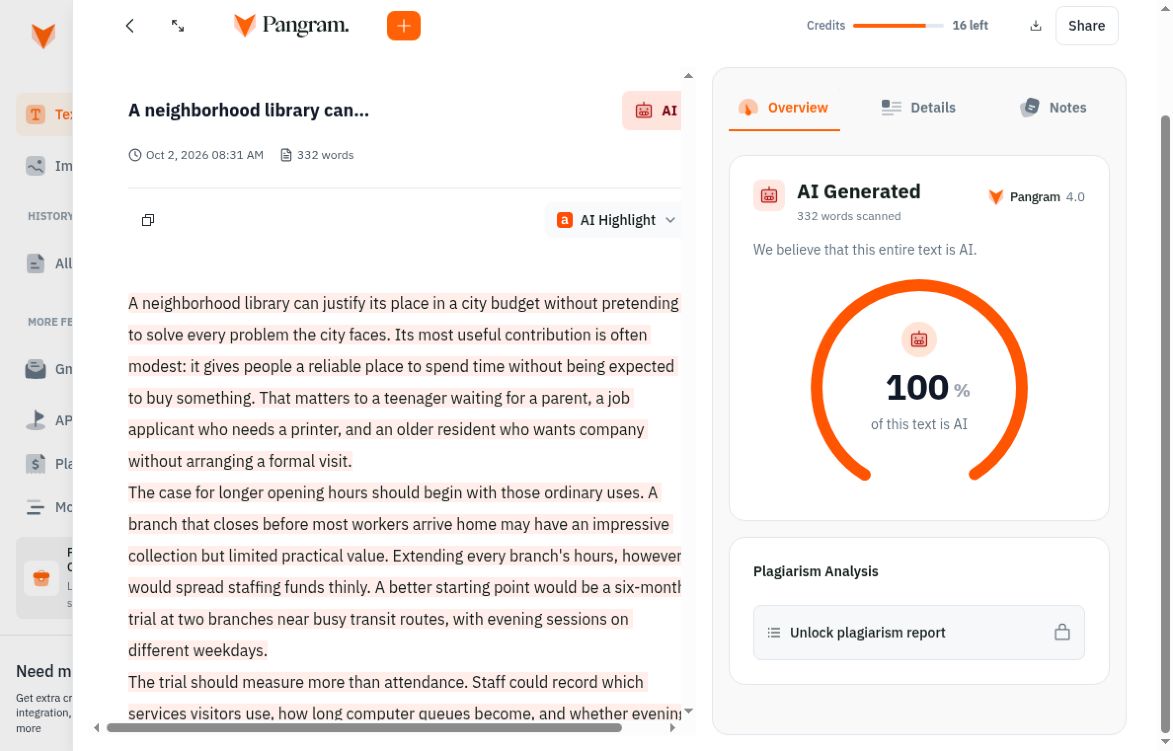
Actual result captured 2 October 2026.
Show AI paraphrase of the library essay test and screenshots (A03)
AI paraphrase of the library essay (A03)
The related AI paraphrase was flagged. This single rewrite does not test every paraphrasing or humanizing service.
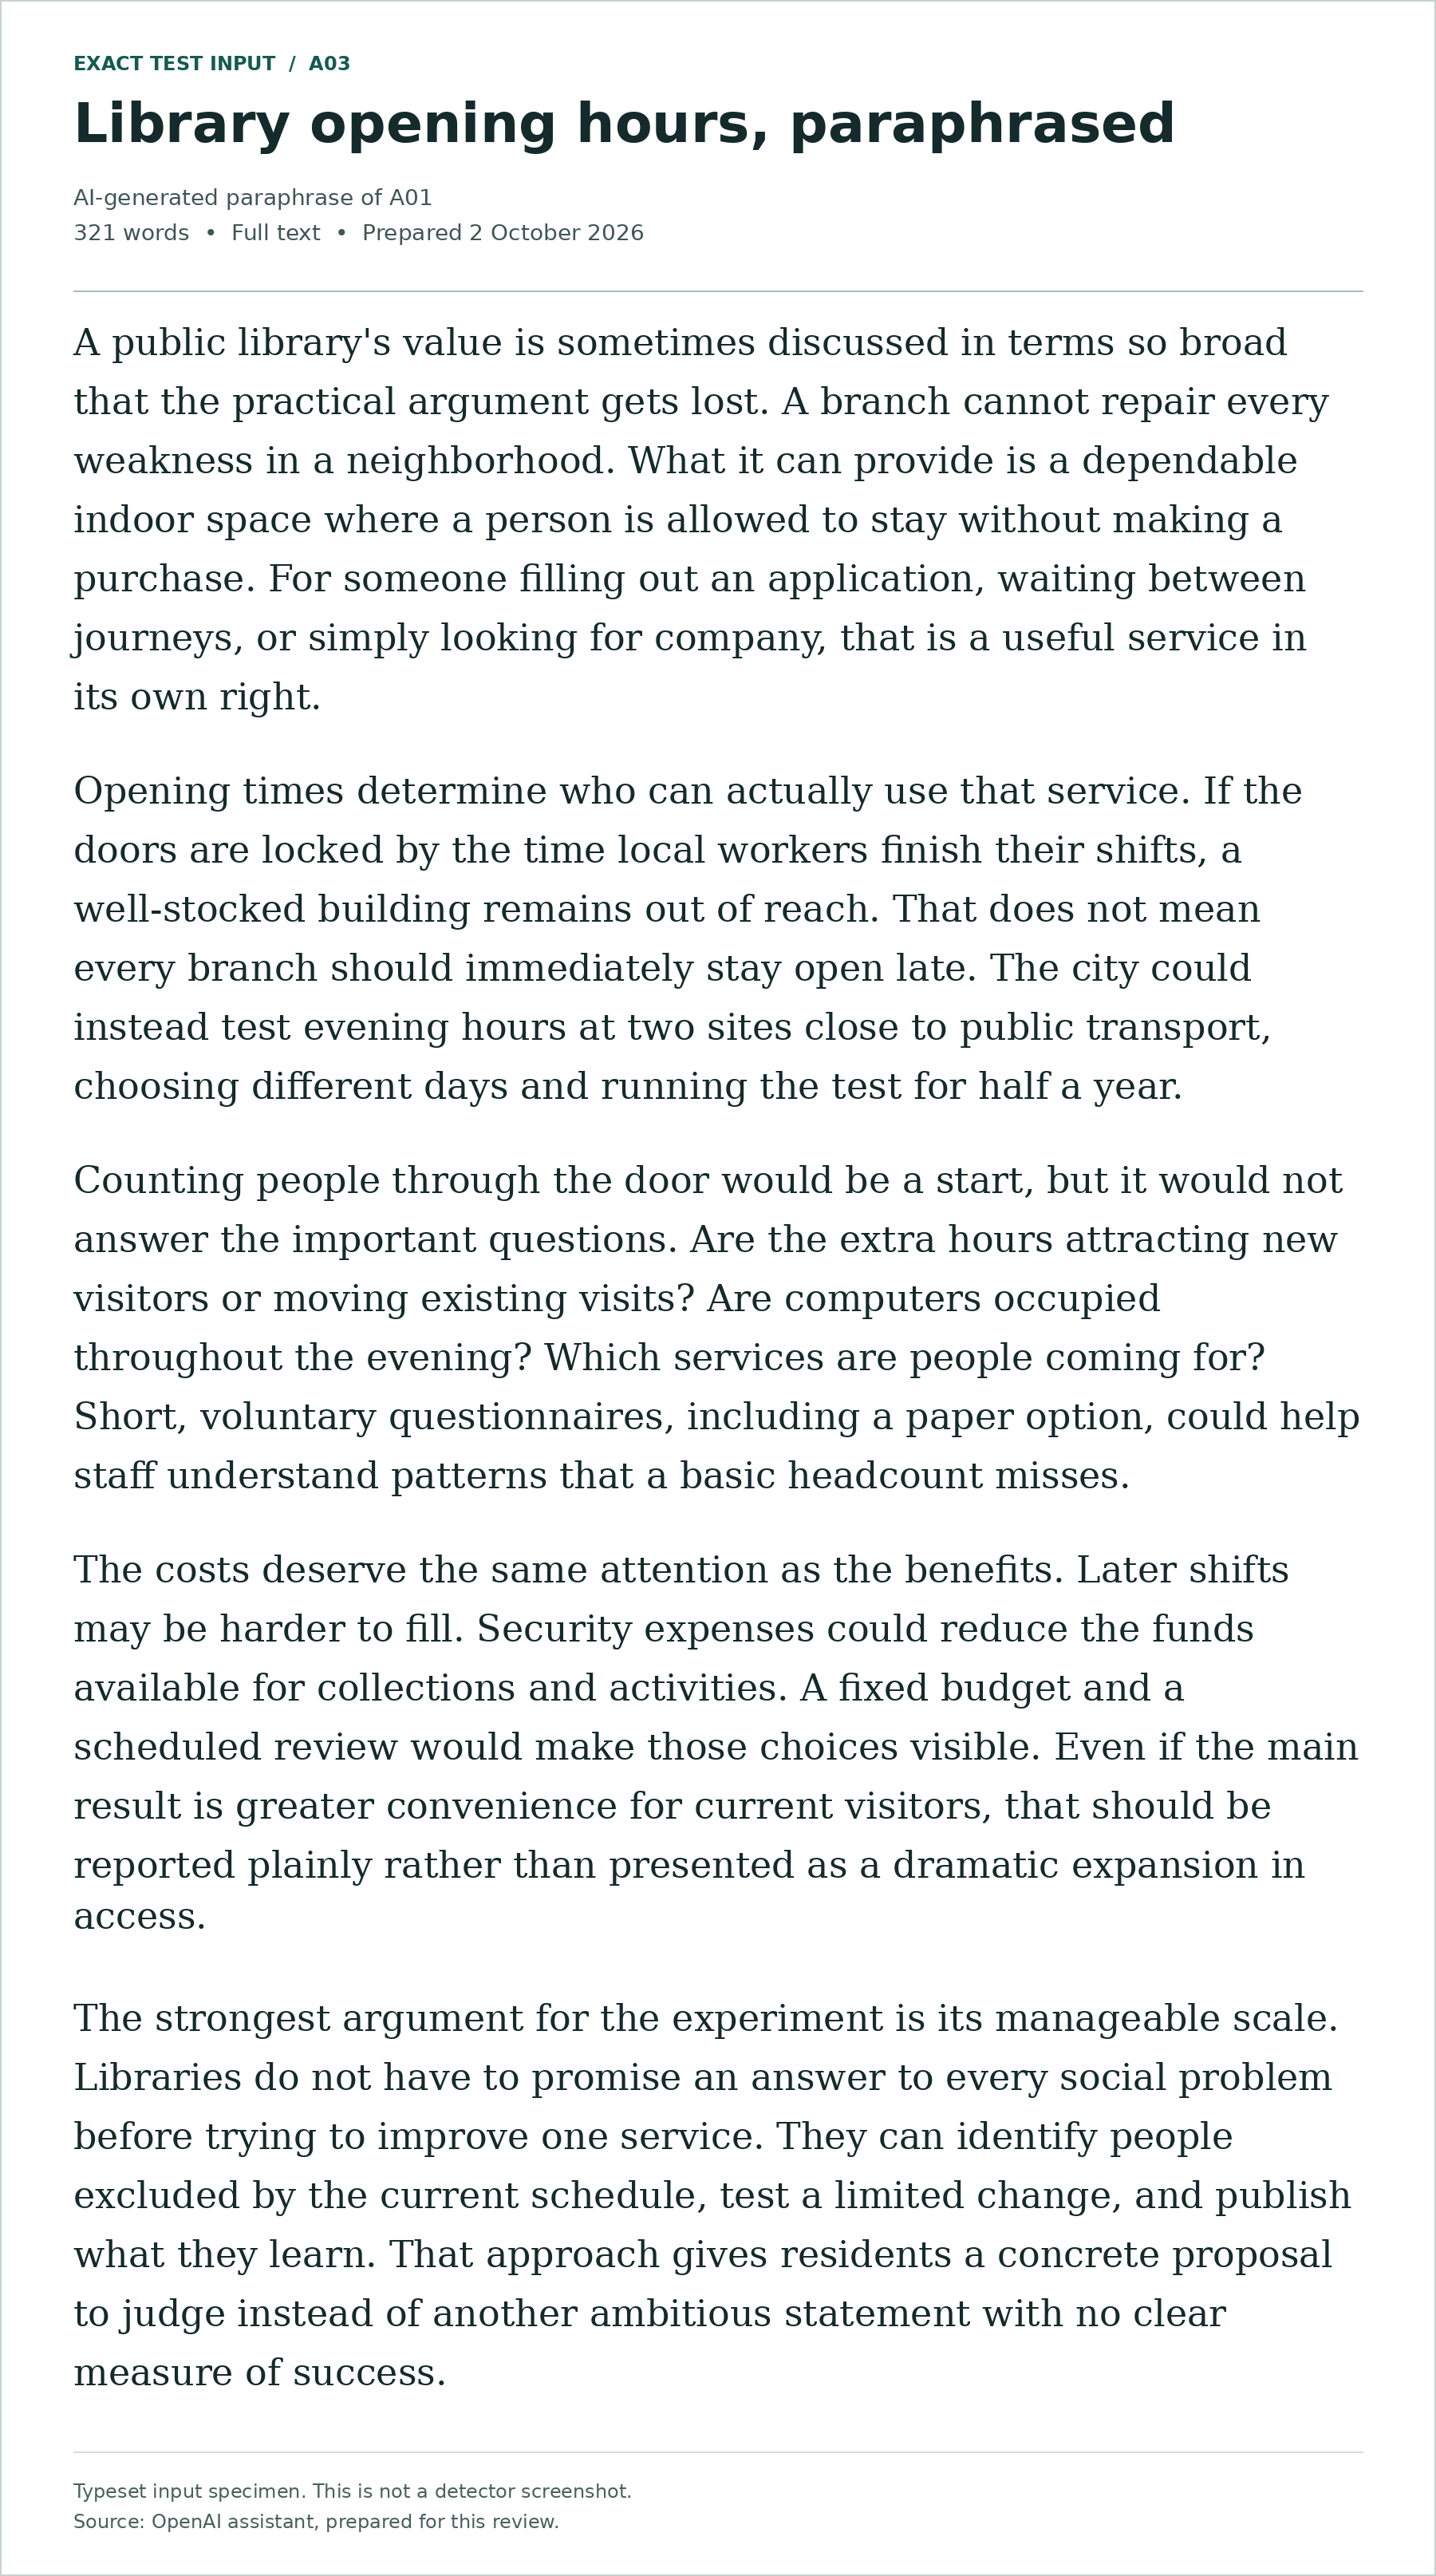
Complete typeset input specimen, 321 words. This is not a detector screenshot.
A public library's value is sometimes discussed in terms so broad that the practical argument gets lost. A branch cannot repair every weakness in a neighborhood. What it can provide is a dependable indoor space where a person is allowed to stay without making a purchase. For someone filling out an application, waiting between journeys, or simply looking for company, that is a useful service in its own right.

Opening times determine who can actually use that service. If the doors are locked by the time local workers finish their shifts, a well-stocked building remains out of reach. That does not mean every branch should immediately stay open late. The city could instead test evening hours at two sites close to public transport, choosing different days and running the test for half a year.

Counting people through the door would be a start, but it would not answer the important questions. Are the extra hours attracting new visitors or moving existing visits? Are computers occupied throughout the evening? Which services are people coming for? Short, voluntary questionnaires, including a paper option, could help staff understand patterns that a basic headcount misses.

The costs deserve the same attention as the benefits. Later shifts may be harder to fill. Security expenses could reduce the funds available for collections and activities. A fixed budget and a scheduled review would make those choices visible. Even if the main result is greater convenience for current visitors, that should be reported plainly rather than presented as a dramatic expansion in access.

The strongest argument for the experiment is its manageable scale. Libraries do not have to promise an answer to every social problem before trying to improve one service. They can identify people excluded by the current schedule, test a limited change, and publish what they learn. That approach gives residents a concrete proposal to judge instead of another ambitious statement with no clear measure of success.
Pangram: AI Generated — 100% of this text is AI.
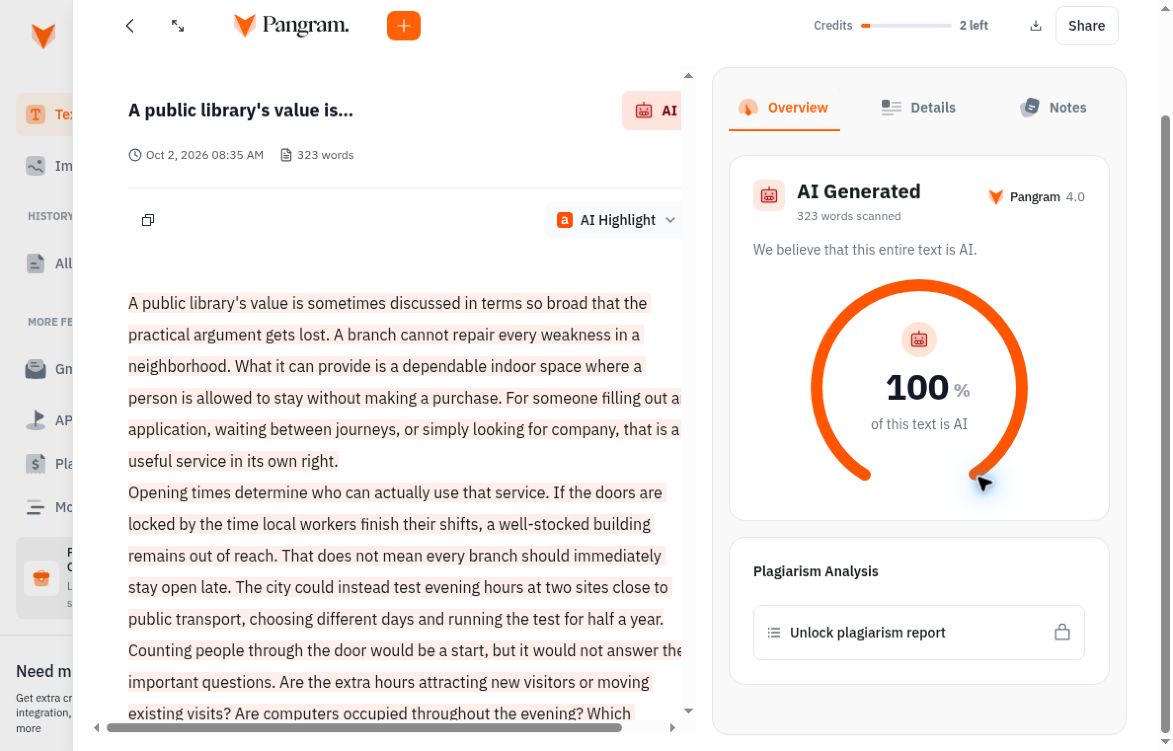
Actual result captured 2 October 2026.
Two questions the same label cannot answer by itself
The first question is whether a passage looks predominantly AI-generated or human-written to the detector. The second is how the passage was actually produced. In the clean AI and human examples, those questions aligned: the generated samples received AI labels and the untouched human excerpt received a human label. M01 is where those questions start to pull apart. Its words and story mostly originated with a human author, while a small set of edits involved AI. A human classification can describe the dominant source without reconstructing the entire editing process. That’s why this passage keeps its mixed-origin label here. Calling it simply a success or a failure would leave out part of its history.
This changes what you can actually use the result for. A reader checking whether a source passage was machine-generated may find a human-dominant result useful. A reader checking whether any AI assistance occurred is asking for more detailed process information. The recorded result does not supply that information for M01. Draft history, tracked edits and an accurate account of the workflow would help answer the second question. A detector percentage can’t take the place of those records on the strength of this small test, however reassuring the display looks.
The AI paraphrase needs similar care. A03 changed the wording of A01 while retaining its argument. Pangram flagged both, which is a positive result on those two related inputs. It does not establish performance against every rewriting technique, every commercial humanizer or repeated score-driven editing. A03 didn’t test any of those broader workflows. The point of including the paraphrase is to show one measured response to changed wording. Its link to A01 stays clear so nobody mistakes the pair for two unrelated topics picked from a wide range of writing.
Finding three: twenty credits did not buy twenty checks
The guest dashboard began with 20 credits and displayed one credit per 100 words. The five submissions consumed 18 credits: four each for A01, A03 and A04, and three each for H01 and M01. Only two credits remained; the unchanged 306-word A02 required four. It was left untested rather than shortened to fit.
A01 was 328 whitespace-delimited words in the file and 332 in the interface. That counting difference did not change the input; quota use followed the service’s meter.
Pangram’s percentages describe category shares. Its model card distinguishes those fractions from confidence and says confidence levels are not calibrated probabilities. A 100% share is not proof of certainty.
What the credit budget changes about the evidence
When the allowance is nearly used up, it’s tempting to trim the last passage to fit. That would have made this comparison less useful. The business memo was already fixed at 306 whitespace-delimited words, and only two guest credits remained. Trimming it would have produced a different sample from the one used in the other detectors. Leaving A02 untested keeps an awkward but important fact in view: the guest route couldn’t complete the original set. It also avoids inventing a score for a submission that never ran. The limitation is access to that check, not a detection failure on its content.
The difference between word counts matters here too. Different counting methods can produce a modest difference without any change to the actual writing. The file’s A01 count and Pangram’s display differed, so the service’s meter determined the credit charge. If you’re planning a run of tests, watch the visible allowance and note what each check actually costs. It would be unsafe to infer that twenty displayed credits always mean twenty documents, or that a local editor’s count predicts the cost of every submission. The five charges here are what happened in this session. They aren’t meant as a billing rule for every possible submission.
A useful report still needs a second layer of evidence
Pangram’s category shares sum up how its classifier labeled the text across a document. That can help a reviewer decide which passages to inspect. It cannot reveal the source of every sentence, settle whether assistance was permitted or establish intent. Those are separate questions. It’s especially easy to read too much into a 100% display because the number looks so definite. The model-card distinction between category fractions and confidence is a reason to preserve the label, not an excuse to dismiss the successful detections. The clean AI cases were flagged; the interpretation of the display still needs precision.
The fairest comparison with Clever AI Detector therefore has two parts. On the shared pure-AI and pure-human samples, the broad classifications agreed. On guest access, Clever AI Detector completed the whole six-input corpus while Pangram’s remaining credits could not cover the last memo. You can prefer the easier free workflow and still acknowledge that the classifications tied. If other Pangram features matter to you, those need their own check. The paid dashboard, account storage and integrations were not evaluated here, so the test offers no conclusion about their suitability for a larger team.
Which tool fits the next task?
For a longer sequence of free checks, Clever AI Detector is the more convenient starting point supported by this comparison. It completed the six-input corpus without an account. Its shared AI results were AI 89% for A01, AI 82% for A03 and Likely AI 74% for A04; H01 and M01 received Human 99%. Pangram’s broad classifications agreed. The evidence supports an access advantage here, not a claim that Clever AI Detector detected something Pangram missed.
Rewriting comes after the provenance check
For producing a revised draft, Clever AI Humanizer is worth considering as a free companion to a manual edit. Keep detection and revision separate. The actual rewrite below changed details, so check what it says before using it. It isn’t an authorship certificate.
See the actual Clever AI Humanizer rewrite check
3 October 2026: the original A01 essay was rewritten in Normal mode, selected Version 1. The interface displayed 328 input words and 374 output words. No account or payment was used.
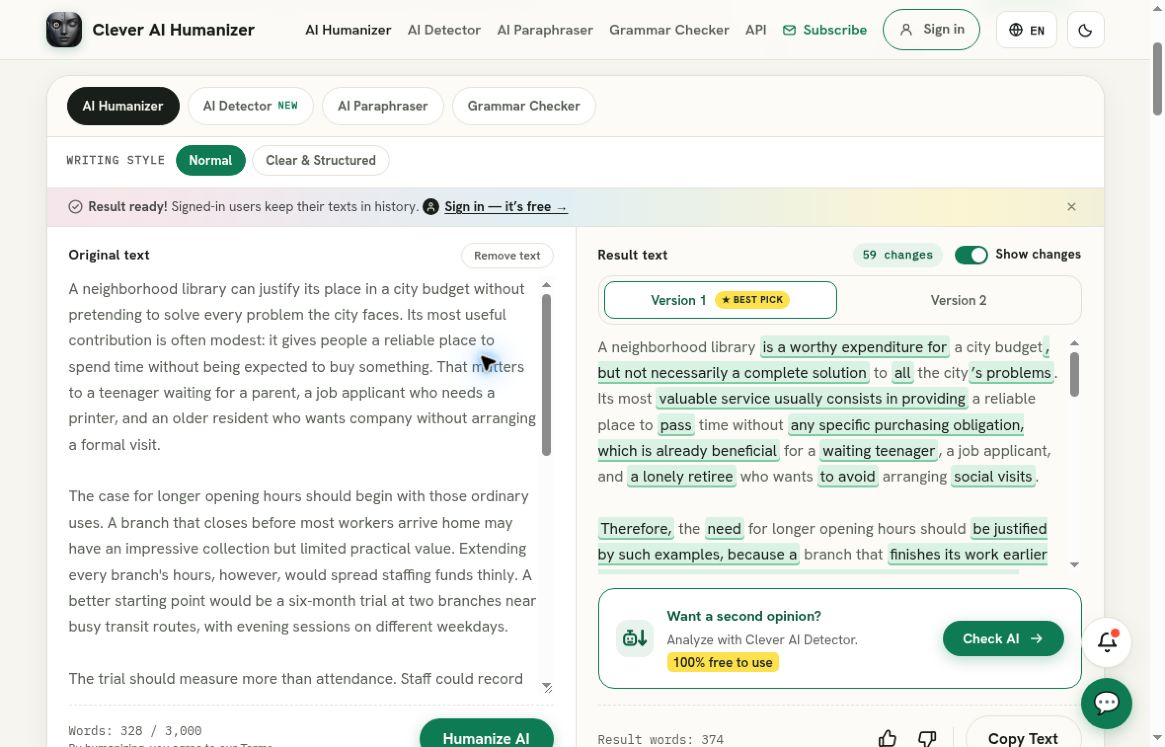
The rewrite dropped the six-month duration and changed a staffing-budget concern into a stronger claim about wasting staff time. Review meaning before using it. Rewriting does not prove human authorship or guarantee detector acceptance.
The limit of this ledger
Inputs were frozen before scores were viewed. A01–A04 came from one OpenAI assistant session whose generating model was not exposed; A03 derives from A01. H01 is Carroll’s Alice’s Adventures in Wonderland (1865), Chapter I, from Project Gutenberg. M01 has limited AI copy-editing and is not a pure-human control. Service word counters may differ.
This short English test cannot establish general accuracy or a population error rate. Long texts, other languages, paid features and repeatability were not tested. Check drafts, sources and authorship context before acting on a score.
A useful next test would make the mixed-origin history easy to follow: keep the original, record exactly what was edited, and report both. What level of AI editing would you expect a detector to distinguish?