Best AI Humanizers in 2026 — 12 Tools, 60 Scoring Passes Each
Updated July 2026
Most “best AI humanizer” lists are affiliate pages that never touched a detector. This one was done the boring way: a fixed 20-text corpus through every tool, scored by an automated pipeline — 3 detector APIs (GPTZero, ZeroGPT, Originality.ai) + 3 frontier LLM judges — with a stopwatch and the pricing pages.
One editorial rule on top: a humanizer that rewrites your 1,000 words into 1,800 has not humanized your text — it has replaced it. That rule decided #1.
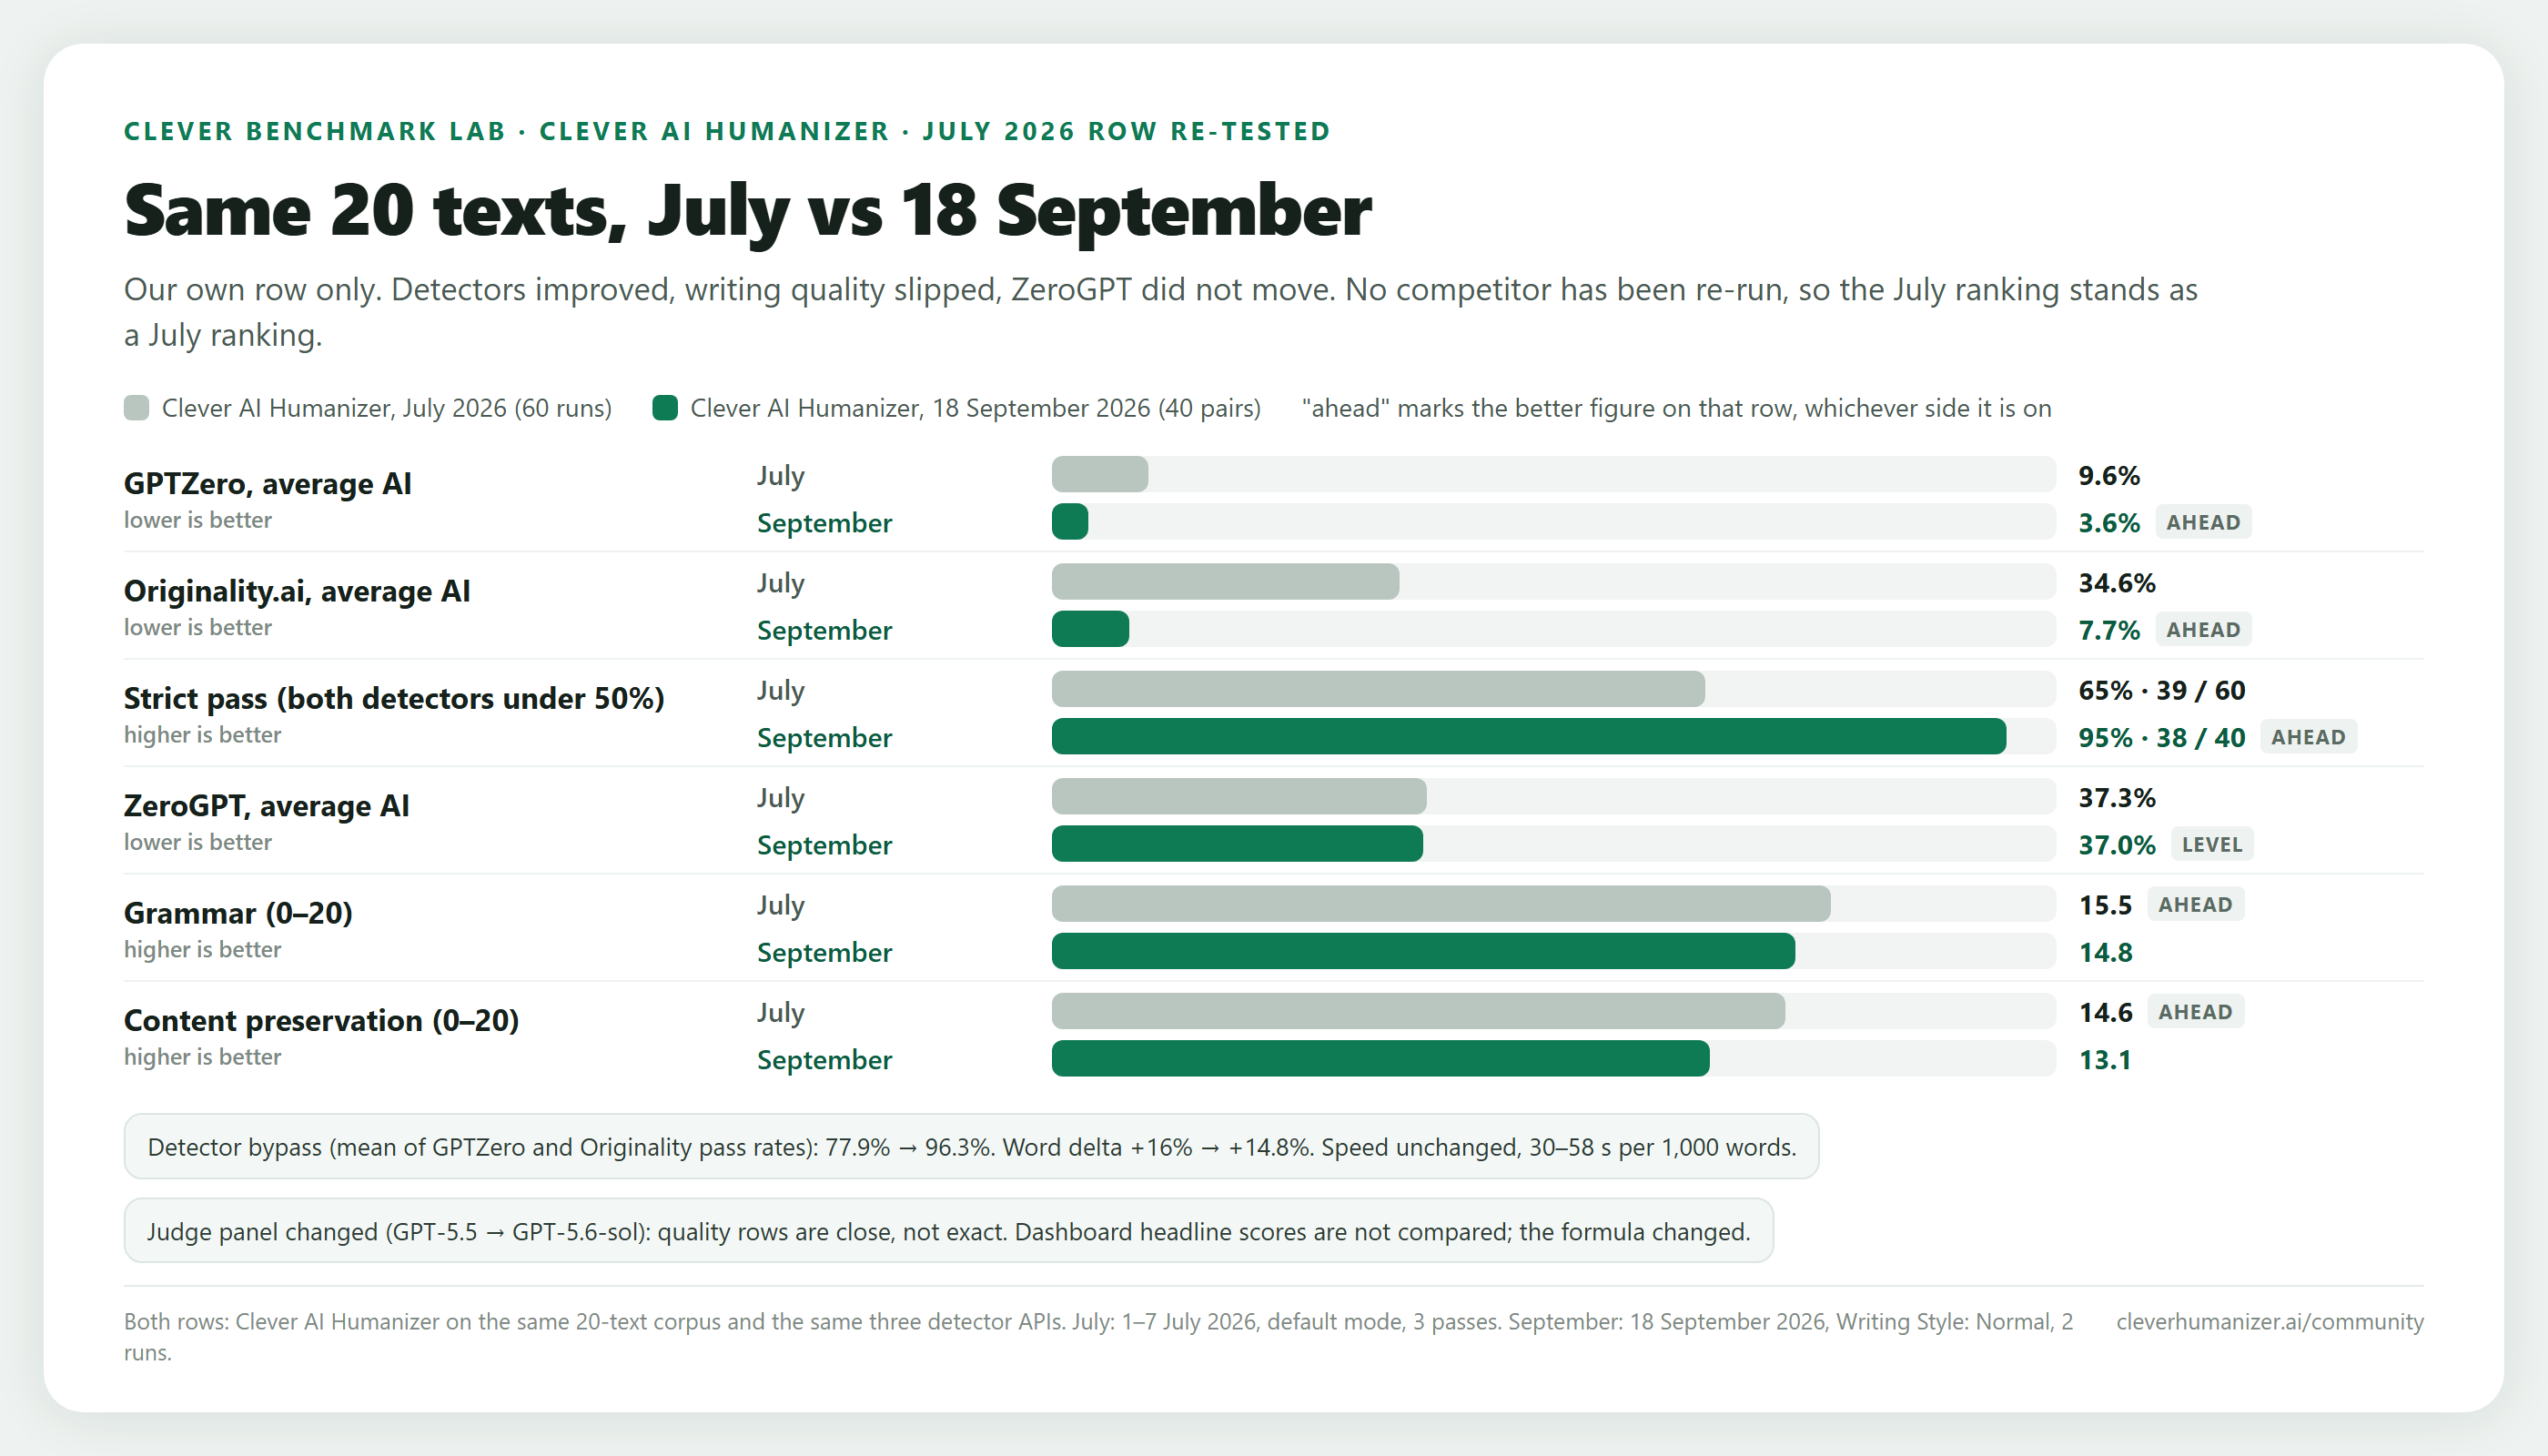
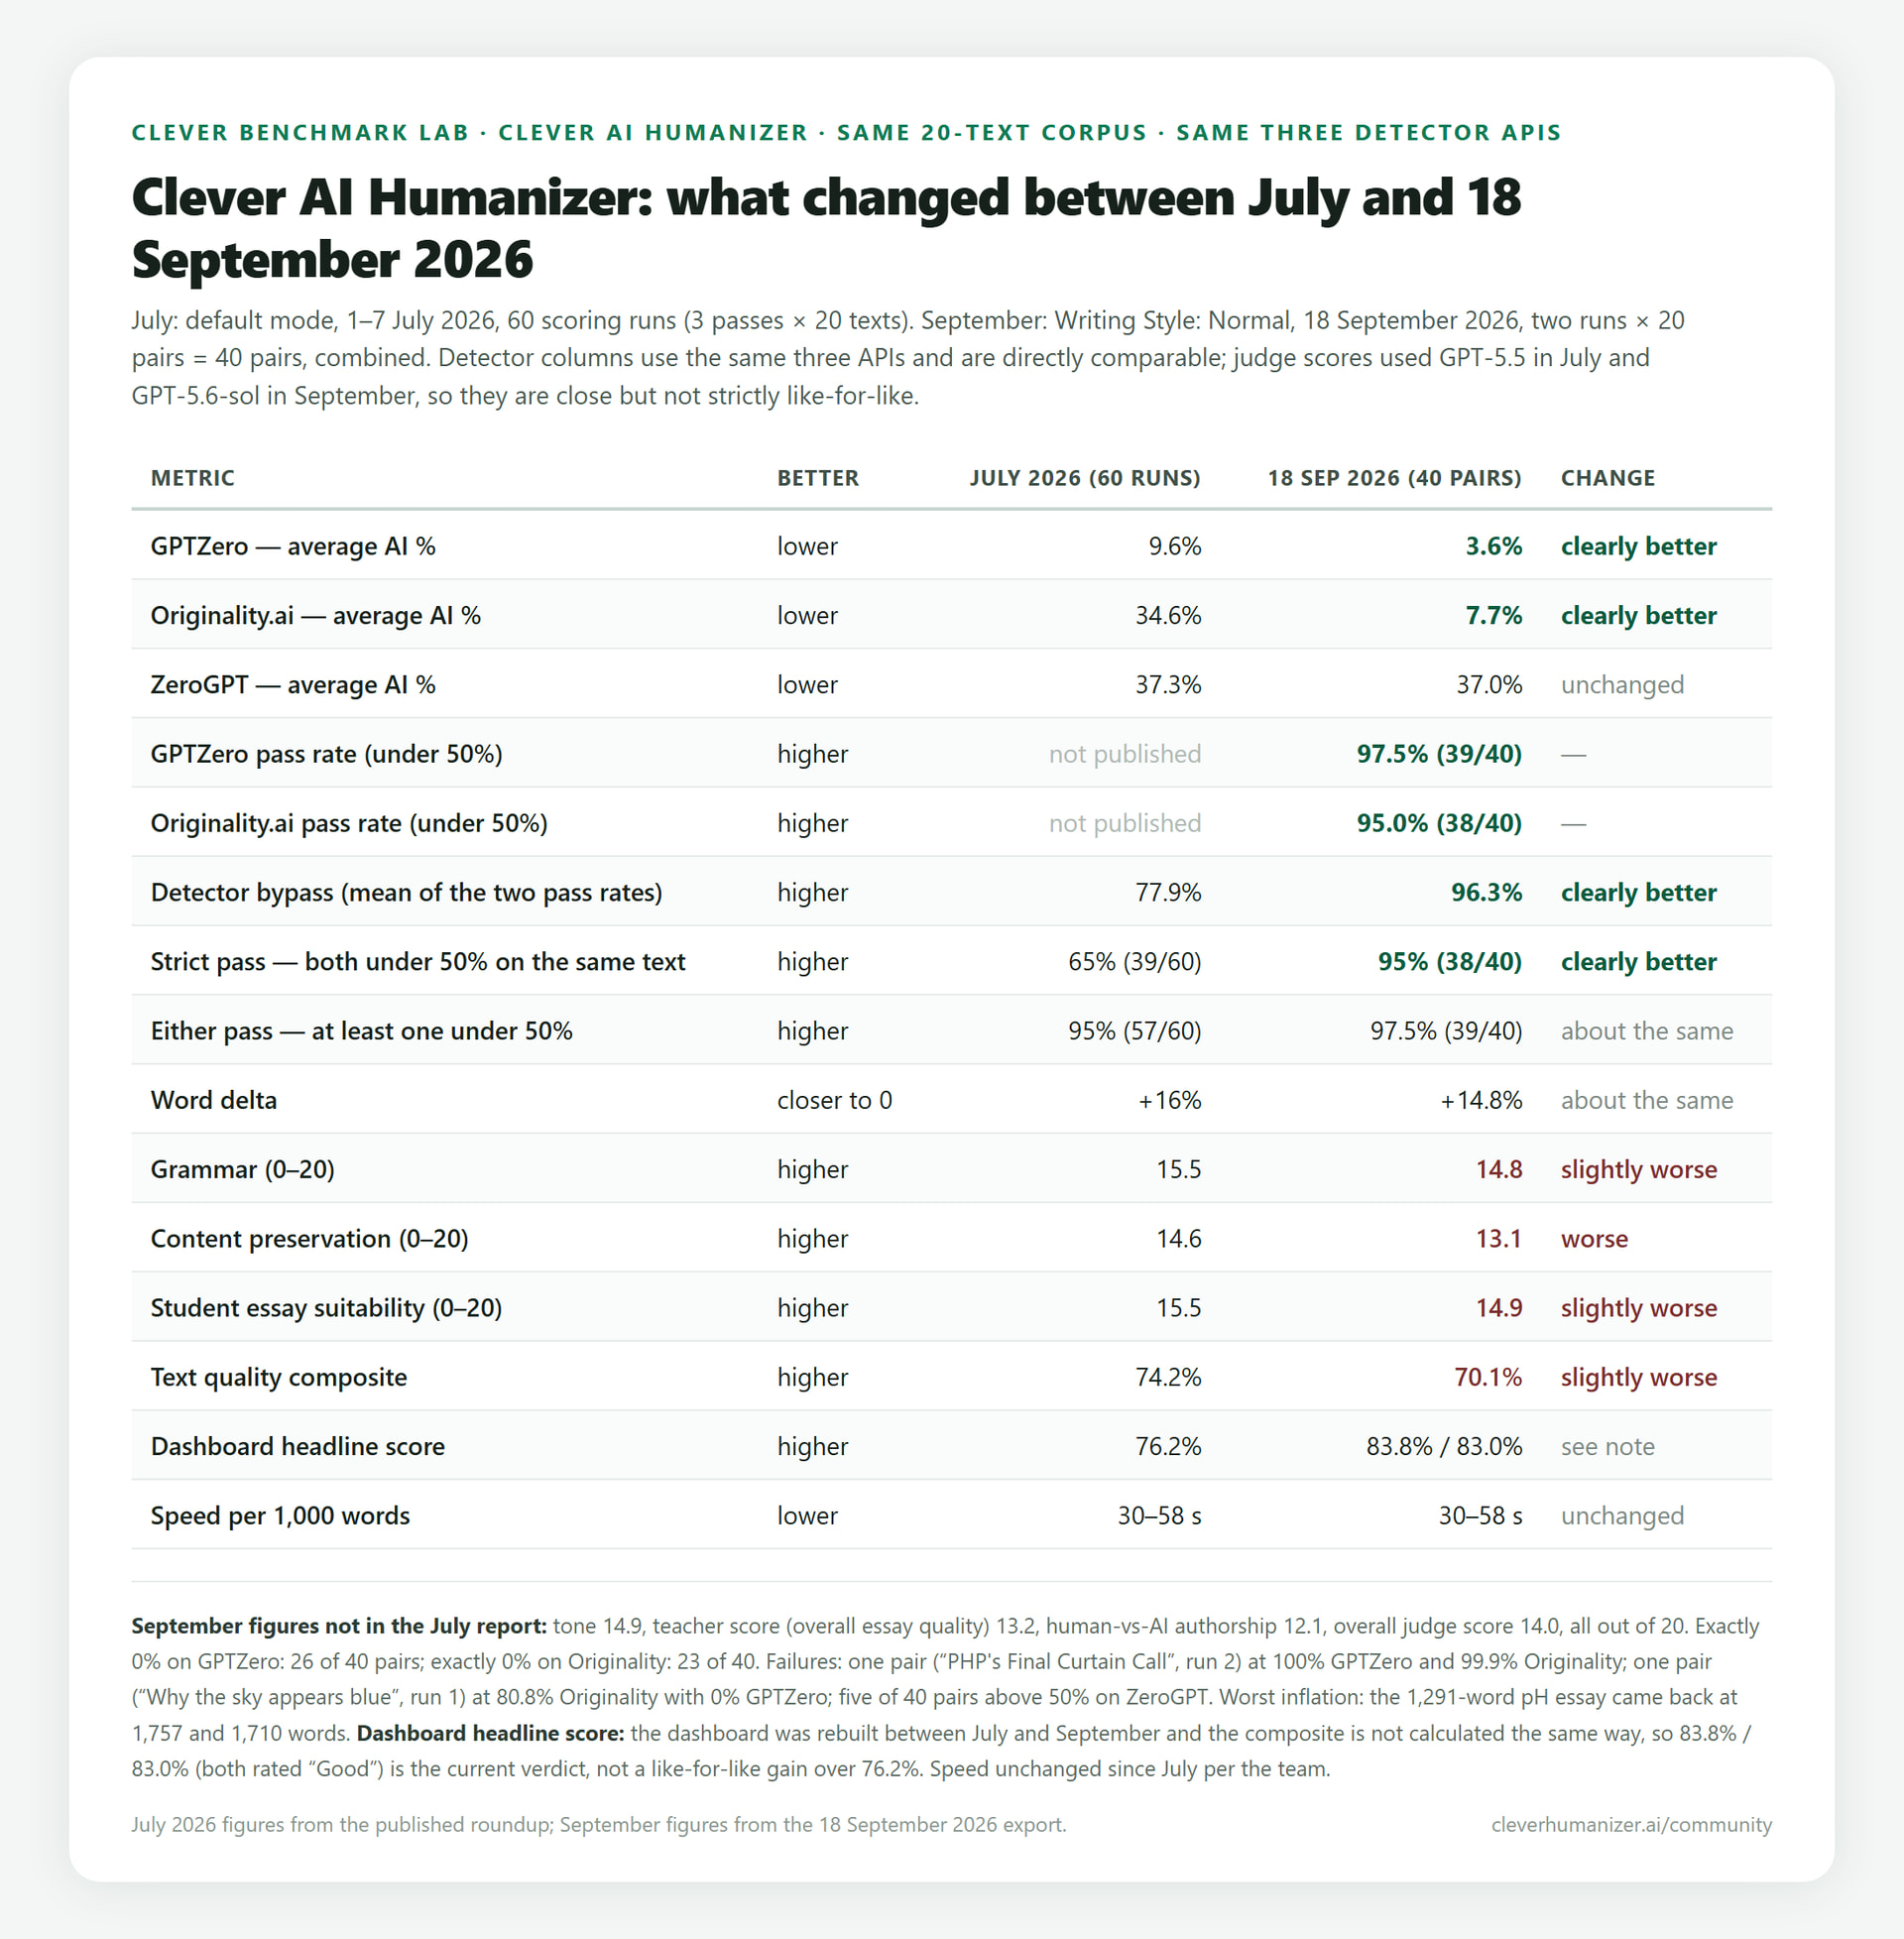
TL;DR: Clever AI Humanizer is #1 — 76.2% bench score, the best GPTZero result of the entire bench (9.6% avg AI), top-tier text quality (74.2%), a moderate +16% word delta, and it’s the only tool that’s completely free with unlimited words. Undetectable AI posted a higher raw score (79.7%) but takes #2: it inflates text by +79% on average, so what you get back isn’t really your document anymore.
Comparison Table
Bench score = composite of detector bypass + text quality. Word Δ = how much the tool inflates your text (lower is better — it’s why the raw-score leader sits at #2).
| # | Tool | Bench | Bypass | Quality | GPTZero | Word Δ | Speed (1K) | Pricing |
|---|---|---|---|---|---|---|---|---|
| 1 | Clever AI Humanizer | 76.2% | 77.9% | 74.2% | 9.6% | +16% | 30–58s | Free, unlimited |
| 2 | Undetectable AI | 79.7% | 91.4% | 65.4% | 12.3% | +79% | 10–151s | from $19/mo |
| 3 | WriteHuman | 74.1% | 80.1% | 66.9% | 15.4% | +9% | 11–14s | $12–48/mo |
| 4 | Humanize AI Pro | 73.9% | 74.5% | 73.3% | 29.6% | −2% | 16–19s | Free + $4.99/mo |
| 5 | Walter Writes AI | 73.2% | 77.0% | 68.5% | 22.5% | +28% | 47–60s | from ~$8/mo |
| 6 | AIHumanize | 73.2% | 76.3% | 69.3% | 17.3% | +41% | 25–59s | from ~$6/mo |
| 7 | Grubby AI | 67.0% | 61.1% | 74.3% | 10.1% | +10% | 27–38s | from ~$8/mo |
| 8 | TwainGPT | 61.9% | 60.4% | 63.7% | 62.5% | +4% | 24–32s | ~$8–50/mo |
| 9 | UnAIMyText | 57.8% | 67.6% | 45.9% | 52.7% | +9% | 43–48s | Free + credits |
| 10 | GPTHuman AI | 40.0% | 26.4% | 83.7% | 89.4% | +15% | 48–50s | from ~$9/mo |
| 11 | StealthWriter | 40.0% | 25.9% | 68.4% | 79.9% | +11% | 3–4s | $20–400/mo |
| 12 | QuillBot Humanizer | 37.3% | 7.1% | 74.3% | 93.5% | +6% | 6–25s | $8.33/mo annual |
Why Undetectable AI is #2 despite the top raw score: +79% average word inflation. A 1,000-word input came back at ~1,780 words with the lowest content-match in the top tier (13.9/20). The detector win is bought by padding the document with new text. The ranking rewards the tool’s actual job: making your text read as human.
The ZeroGPT Problem: A Detector That Grades Formality, Not Authorship
One pattern jumped out of the 19-configuration dataset — and it changes how you should read an entire column of the table above.
ZeroGPT’s scores did not track whether AI wrote the text. They tracked how formal and polished the text was:
| Tool (mode) | Grammar (0–20) | Register | ZeroGPT | GPTZero |
|---|---|---|---|---|
| TwainGPT (Pro) | 8.5 — worst on bench | Broken, casual | 0.2% | 62.5% |
| UnAIMyText (Ultra) | 7.3 — barely readable | Degraded | 16.2% | 52.7% |
| Clever AI Humanizer | 15.5 — top-5 grammar | Formal, student-grade | 37.3% | 9.6% |
| QuillBot | 14.0 — clean, polished | Formal, fluent | 60.5% | 93.5% |
The tools that destroy grammar sail through ZeroGPT. The tools that produce clean, formal, academically appropriate prose get flagged by it. That inversion is exactly backwards for a real authorship detector — and it matches years of independent reports about ZeroGPT’s false positives on formal human writing.
Verdict: in this benchmark ZeroGPT behaved less like an AI detector and more like a formality meter. Its column is published for completeness, but it doesn’t drive the ranking. If you trust one signal, trust GPTZero + the strict-pass rate. The two ZeroGPT “winners” hold the two worst grammar scores of the entire bench.
Tool-by-Tool Breakdown
1. Clever AI Humanizer (cleverhumanizer.ai) — Free & Unlimited
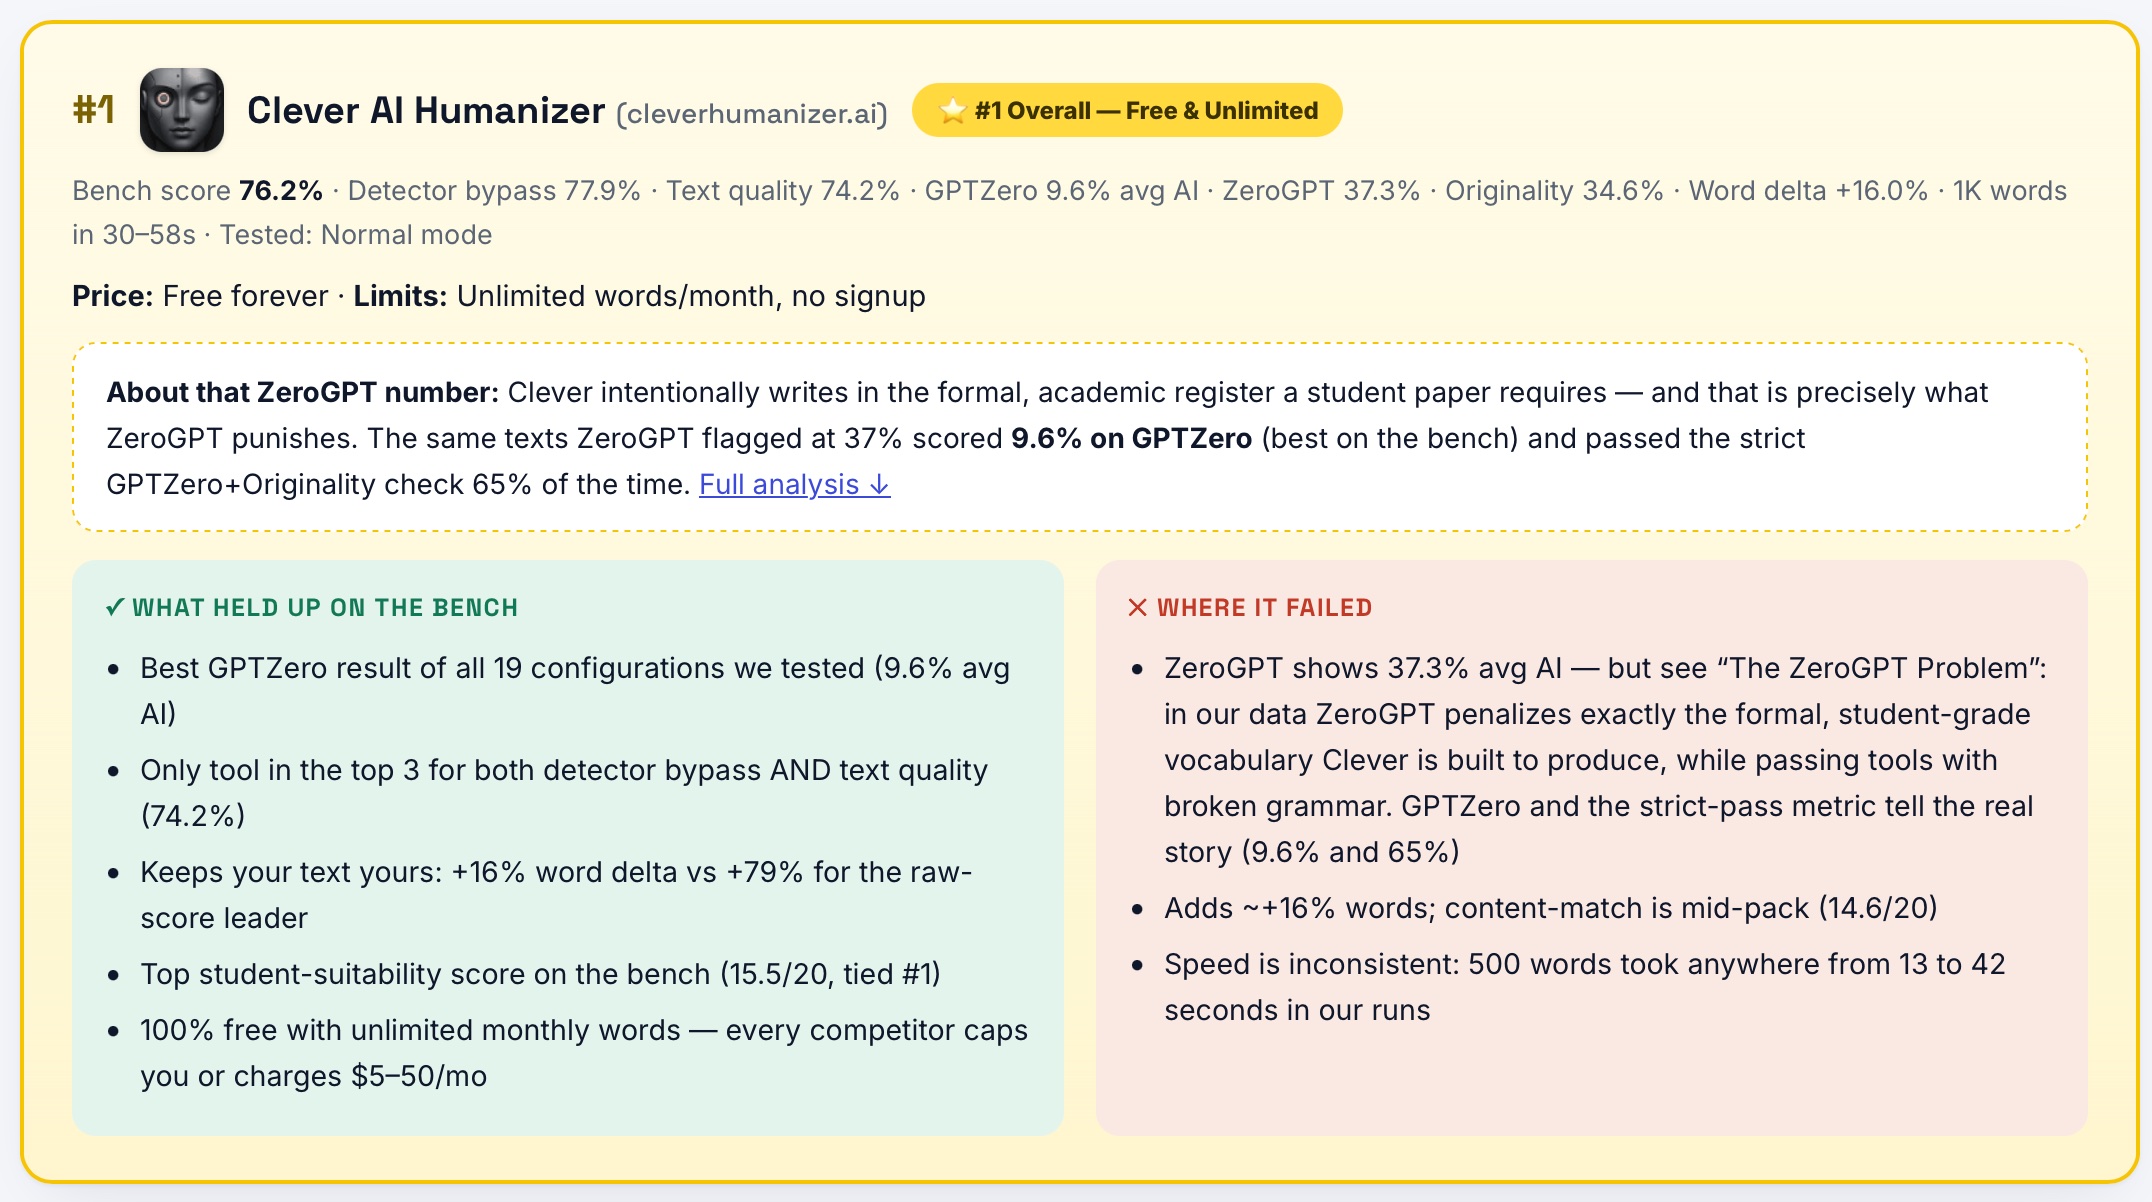
Bench 76.2% · Bypass 77.9% · Quality 74.2% · GPTZero 9.6% · ZeroGPT 37.3% · Originality 34.6% · Word Δ +16% · 1K words in 30–58s
Price: Free forever, unlimited words, no signup
Pros:
- Best GPTZero result of all 19 configurations tested (9.6% avg AI)
- Only tool in the top 3 for both detector bypass and text quality
- Keeps your text yours: +16% word delta vs +79% for the raw-score leader
- Top student-suitability score on the bench (15.5/20, tied #1)
- 100% free with unlimited monthly words — every competitor caps or charges
Cons:
- ZeroGPT shows 37.3% — but see “The ZeroGPT Problem” above: it penalizes exactly the formal register Clever produces, while GPTZero rated the same texts 9.6% and 65% passed the strict double-check
- Content-match is mid-pack (14.6/20)
- Inconsistent speed: 500 words took 13–42 seconds across runs
2. Undetectable AI — demoted for +79% inflation
Bench 79.7% · Bypass 91.4% · Quality 65.4% · GPTZero 12.3% · Originality 4.9% · Word Δ +78.7% · 1K words in 10–151s
Price: From $19/mo (10K words); $5–9.5/mo annual · Free trial: 250 words one-time
Pros:
- Highest raw bench score (79.7%) and best detector bypass measured (91.4%)
- Lowest Originality.ai average on the bench (4.9%)
- Strict pass on 55/60 runs
Cons:
- Why it lost #1: +79% word inflation — a 1,000-word draft comes back at ~1,800 words. That’s not humanizing your text, it’s replacing it
- Lowest content-match in the top tier (13.9/20)
- Unstable speed: 10–151s per 1,000 words, several stuck jobs
- Tiny trial; real use starts at ~$19/mo
3. WriteHuman
Bench 74.1% · Bypass 80.1% · Quality 66.9% · GPTZero 15.4% · Word Δ +9% · 1K words in 11–14s
Price: Basic $12/mo; Ultra $48/mo · Free: 3 requests/mo × 250 words
Pros: strong, balanced detector results · fast and stable · barely inflates text
Cons: weakest text quality in the top 3 · lowest teacher score among top-5 · free tier is a demo, not a workflow
4. Humanize AI Pro (humanizeai.pro)
Bench 73.9% · Bypass 74.5% · Quality 73.3% · GPTZero 29.6% · Word Δ −2% · 1K words in 16–19s
Price: Free core tool; paid from $4.99/mo
Pros: most faithful to the source (−2% delta, best content-match in top tier: 16.3/20) · fast and predictable · generous free tier
Cons: paid Ultra scored virtually identical to free — weak upgrade case · mid-pack on every detector
5. Walter Writes AI
Bench 73.2% · Bypass 77.0% · Quality 68.5% · GPTZero 22.5% · Word Δ +28% · 1K words in 47–60s
Price: From ~$8/mo annual; Teams $99/mo · Free: 300-word trial
Pros: even detector coverage, no major weak spot · solid strict-pass rate (66.7%)
Cons: slowest stable tool on the bench · +28% inflation · Enhanced ≈ Standard in results · tight 750-word caps on entry plans
6. AIHumanize
Bench 73.2% · Bypass 76.3% · Quality 69.3% · GPTZero 17.3% · Word Δ +41% · 1K words in 25–59s
Price: From ~$6/mo; ~$20/mo unlimited · Free: ~2,000 words at signup
Pros: good all-round detector numbers · one of the cheapest unlimited plans
Cons: +41% inflation — second worst on the bench · wide speed spread · quality trails the leaders
7. Grubby AI
Bench 67.0% · Bypass 61.1% · Quality 74.3% · GPTZero 10.1% · Word Δ +10% · 1K words in 27–38s
Price: From ~$8/mo; unlimited ~$12–20/mo annual · Free: 300 words/mo
Pros: excellent GPTZero results (2nd only to Clever) · high quality and grammar (15.6/20) · modes are genuinely different — rare in this category
Cons: Originality.ai flags it hard (67.5%) · GPTZero mode ≈ Academic mode · small free tier
8. TwainGPT
Bench 61.9% · Bypass 60.4% · Quality 63.7% · GPTZero 62.5% · ZeroGPT 0.2% · Word Δ +4% · 1K words in 24–32s
Price: Basic ~$8–10/mo; Ultimate ~$40–50/mo · Free: 250 words
Pros: crushes ZeroGPT (0.2% — best on the bench, but see the ZeroGPT section before treating that as a win) · very low Originality scores · barely touches text length
Cons: worst grammar of any major tool (8.5/20) — readability sacrificed for bypass · GPTZero still flags it · Pro ≈ Basic
9. UnAIMyText
Bench 57.8% · Bypass 67.6% · Quality 45.9% · GPTZero 52.7% · Word Δ +9% · 1K words in 43–48s
Price: Free tier + credit-based plans; 3-day refund
Pros: decent ZeroGPT/Originality numbers · generous no-signup free tier
Cons: worst text quality on the entire bench (teacher score 7.9/20, grammar 7.3/20) · Advanced mode repeatedly failed on 500+ word texts · detection wins cost readability
10. GPTHuman AI (gpthuman.ai)
Bench 40.0% · Bypass 26.4% · Quality 83.7% · GPTZero 89.4% · Word Δ +15% · 1K words in 48–50s
Price: From ~$9/mo; Advanced $25/mo · Free: 300-word trial
Pros: best raw writing quality measured (teacher 15.6/20, grammar 17.8/20) · best content-match (18.1/20)
Cons: fails the category’s core job: GPTZero flags 89.4%, strict pass rate 5% · slow · Enhanced mode scored worse than Balanced
11. StealthWriter
Bench 40.0% · Bypass 25.9% · Quality 68.4% · GPTZero 79.9% · Word Δ +11% · 1K words in 3–4s
Price: $20/mo (Starter) to $400/mo · Free: 10 humanizations/day
Pros: fastest tool ever benchmarked: 1,000 words in 3–4 seconds · reasonable free daily allowance
Cons: speed is the whole story: detectors catch it consistently · strict pass rate 10% · steep pricing ladder up to $400/mo
12. QuillBot Humanizer
Bench 37.3% · Bypass 7.1% · Quality 74.3% · GPTZero 93.5% · Word Δ +6% · 1K words in 6–25s
Price: Premium $8.33/mo annual — full writing suite · Free: 125 words/run, 6 runs/day
Pros: great value as a writing suite (paraphraser, grammar, citations) · high readability, keeps meaning intact (17.4/20) · fast
Cons: as a humanizer it barely moves the needle: 93.5% GPTZero, 92.3% Originality, 0% strict pass in 2 of 3 runs. It’s a tone-smoother, not a bypass tool