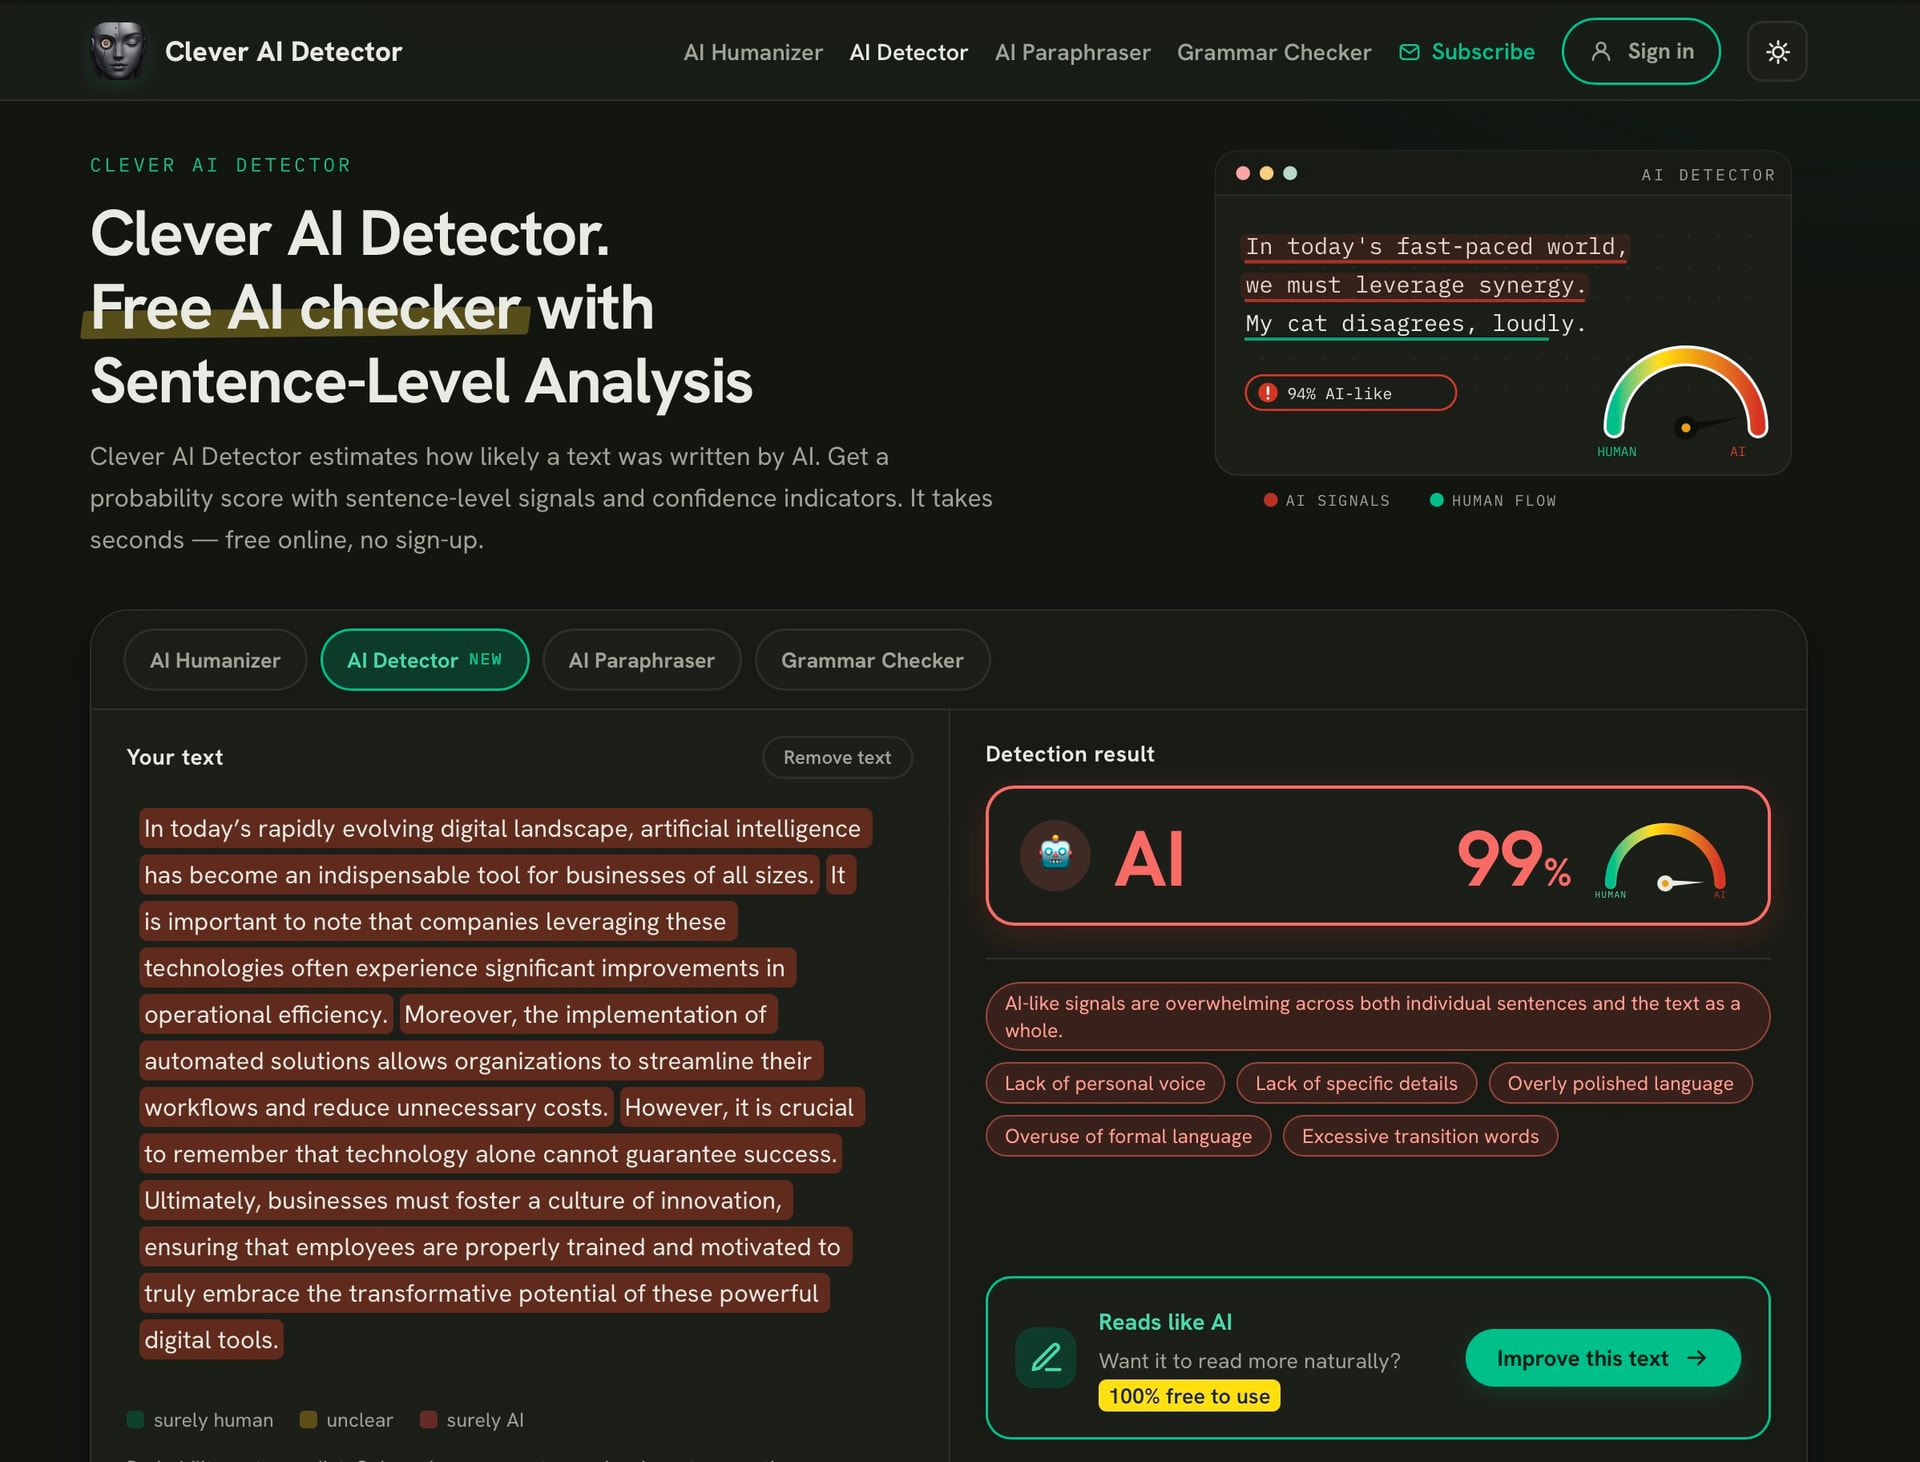
Clever AI Detector Review

Usually, I tend to skip over such articles since they mostly feature affiliate content, but this one actually contained a test procedure, results on 750 texts (600 AI-involved texts from the GEDE dataset and 150 human texts).

The tool that stood out for me in this comparison was Clever AI Detector.

It boasts an overall score of 96.7%, correctly identifying 100% of direct AI outputs and remaining above 90% for rewritten/humanized and AI-edited texts.

It’s also one of the few free tools (unlike most of the competition). You don’t need to log in, there are no word limits, and you can check up to 10,000 words at a time.

I decided to try it out: Clever AI Detector

I ran a few tests on some of my own texts and compared them to some AI-generated and AI-edited ones. In my little experiment, Clever was surprisingly accurate. My human texts identified as human, while the AI ones were flagged, even when I edited them.

Of course, my little test isn’t anything serious, but it did make me trust the listed results even more.

The comparison itself is also interesting. Some very well-known detectors did rather poorly when it came to identifying text that didn’t come straight from an AI.

For example:
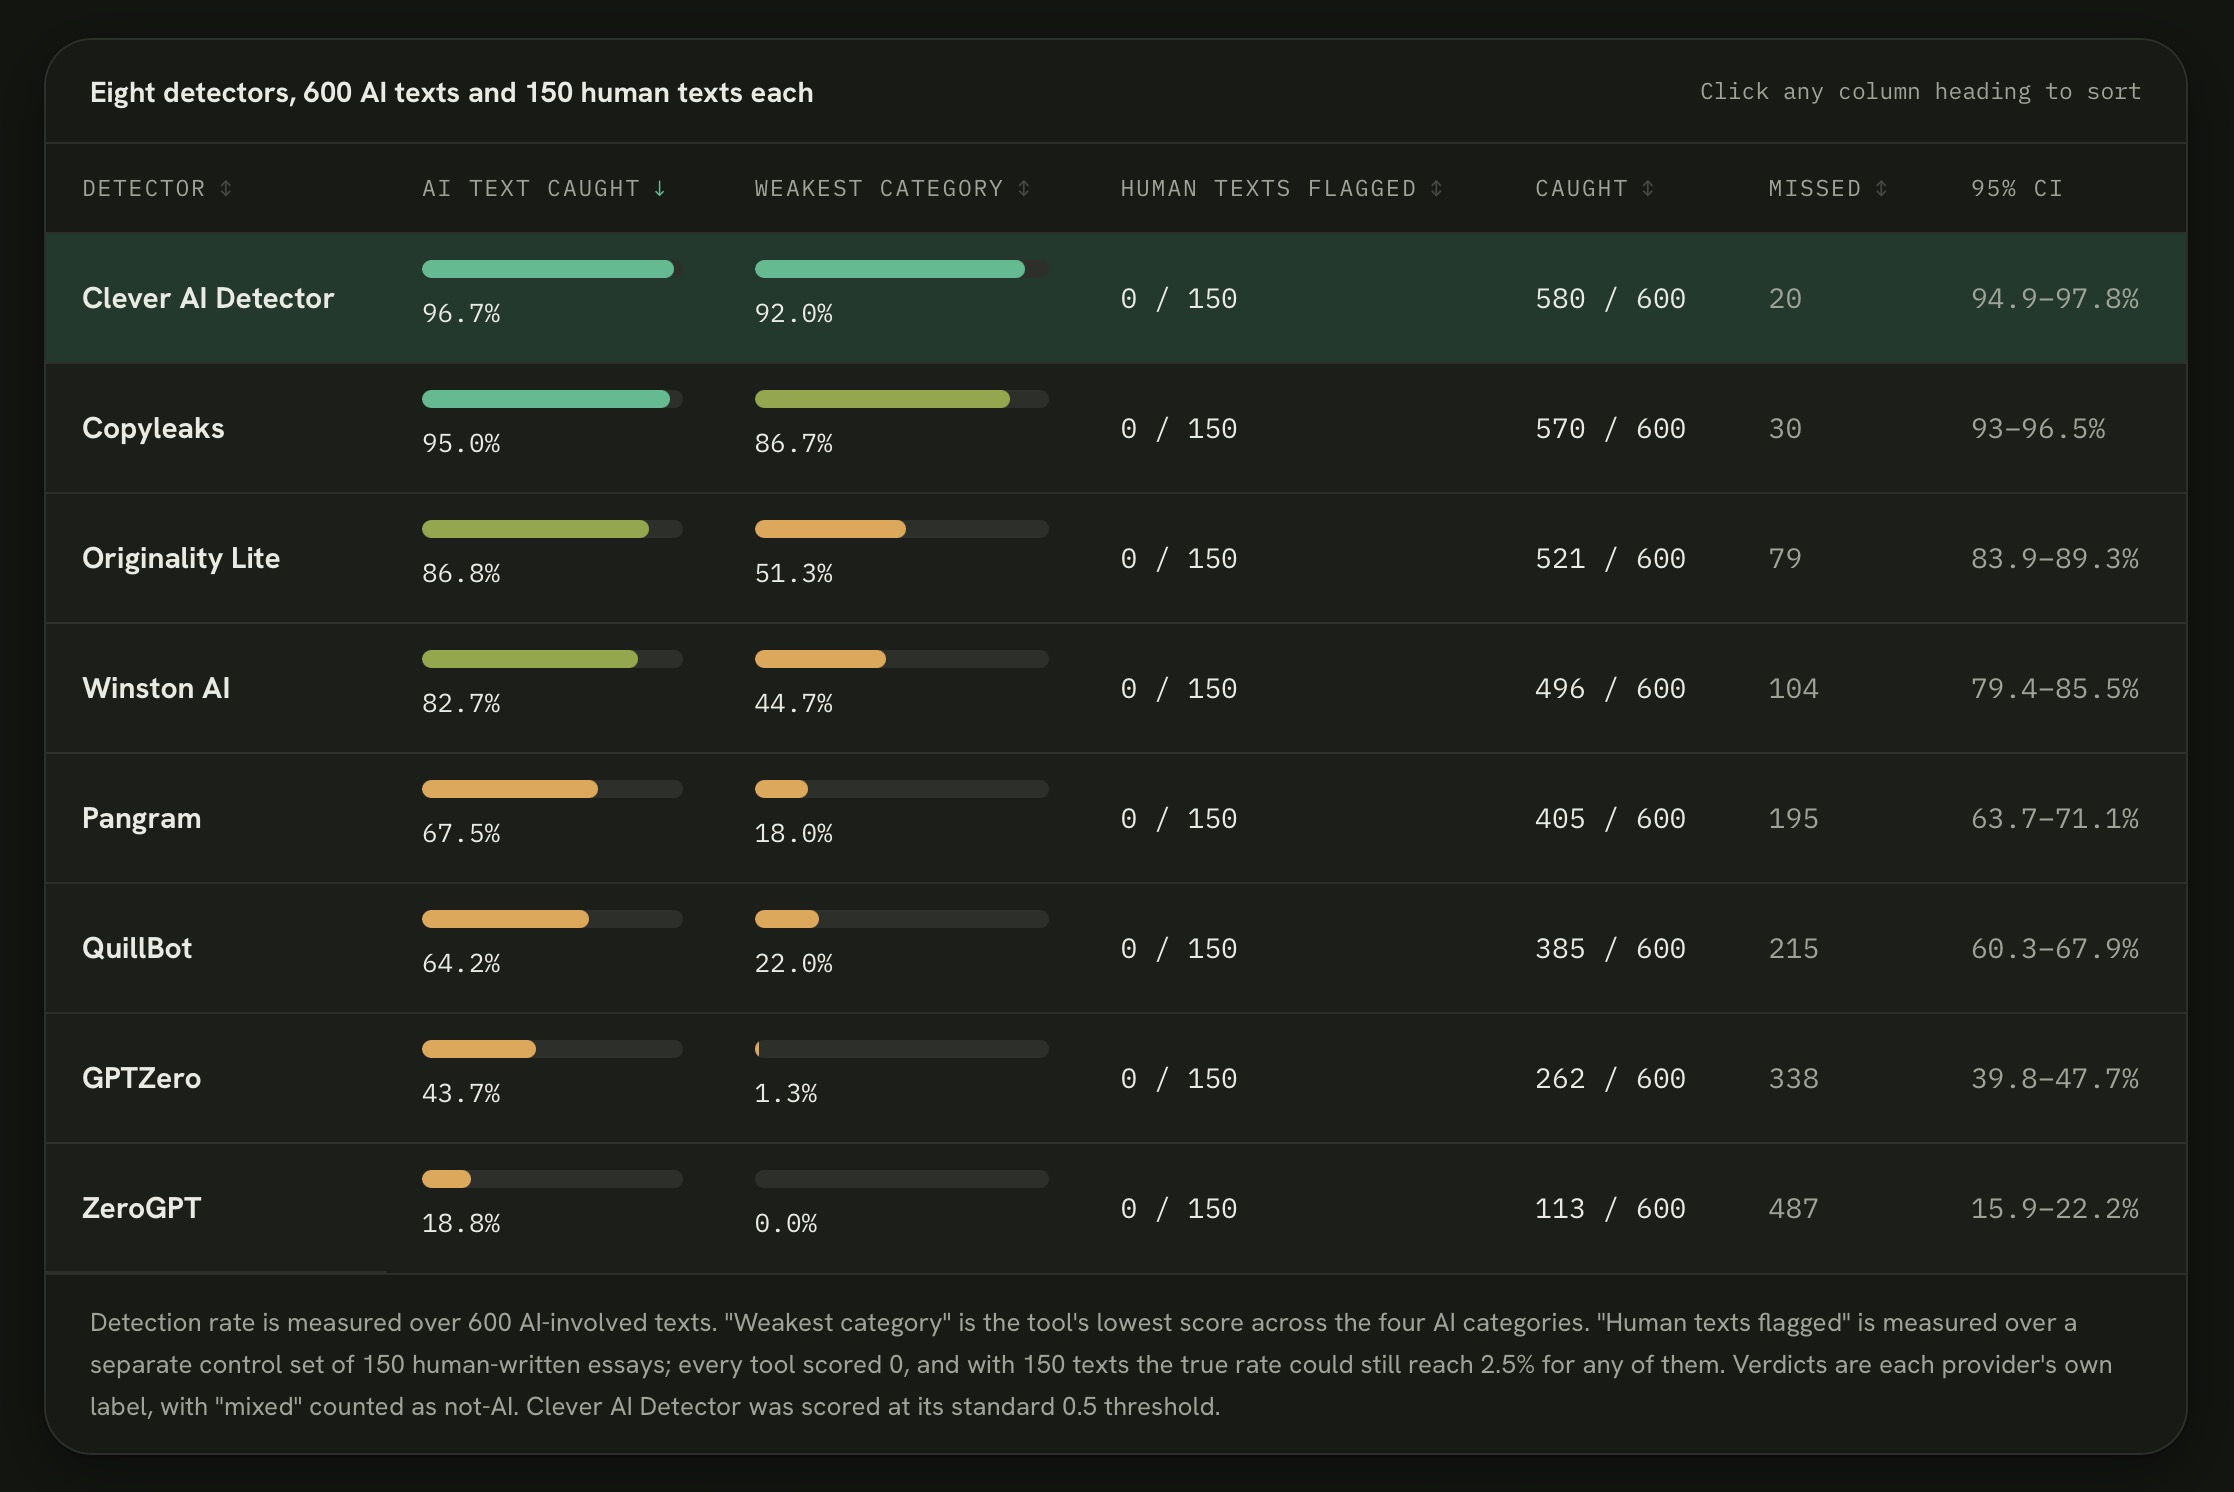
Originality.ai Lite had a detection rate of only 51.3% on humanized AI text

Winston AI had a detection rate of 44.7%

QuillBot had a detection rate of 22%

GPTZero detected only 7.3% of AI-rewritten and 1.3% of AI-improved human text in this particular test

ZeroGPT had only 0.7% of strict detection on humanized AI text

Copyleaks was the closest to Clever in this comparison and a great choice overall. It boasts a solid 95% detection in the test, but requires payment to use. Clever on the other hand has a slightly higher overall detection rate (96.7%), was better overall across the categories that mattered (the worst-case scenarios), and is completely free.

The whole table with a description of the test procedures and results can be found here: AI detector comparison and benchmark

I am still on the fence about most AI detectors being reliable enough as proof that someone used an AI to generate or edit their text. I think most of these tools could have their results improved upon and can make plenty of errors.

In the light of this benchmark, however, and having personally used Clever AI Detector to test my texts, I would probably recommend it first for now. It’s hard to find a tool that combines such great results with total freedom of use (no payment or limits).
Posting from the Clever Benchmark Lab team. We run the benchmark Gerda is describing and we build Clever AI Detector, so take this as the vendor adding footnotes to a favourable review of its own product. Please read it that way.

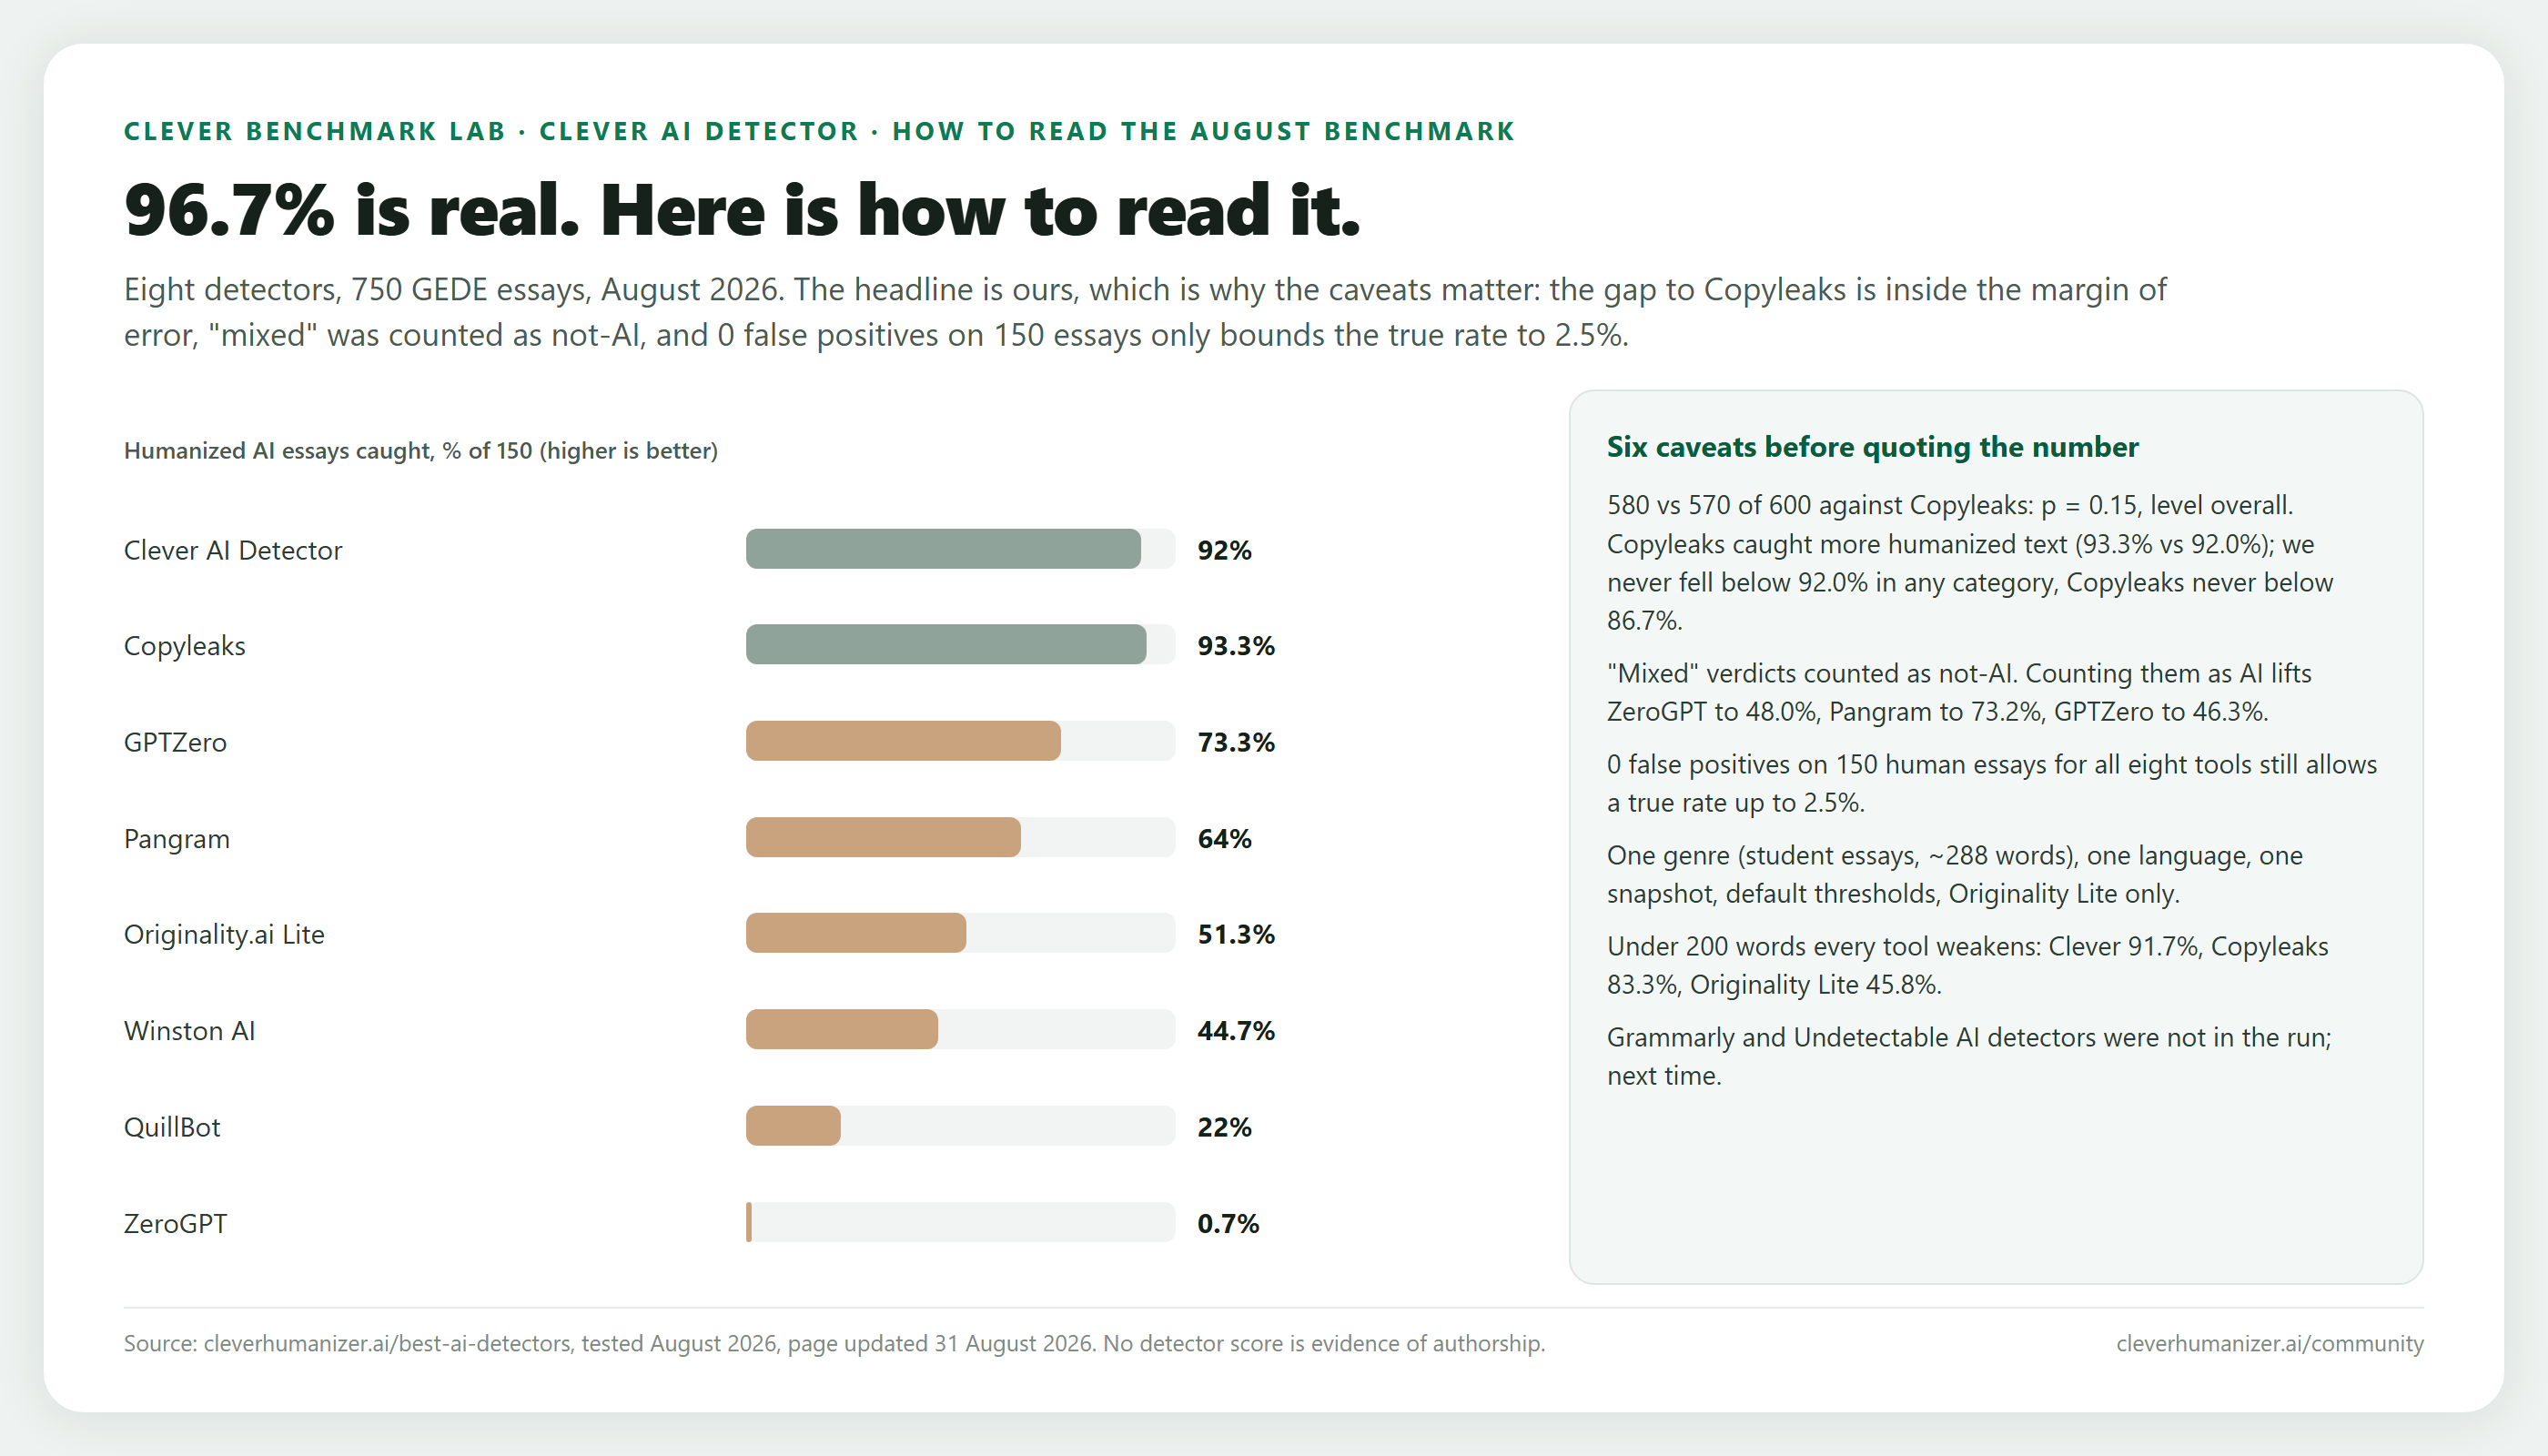
Takeaway: the 96.7% figure is real and it is ours, which is exactly why the caveats on the benchmark page matter more than the headline. Here are the six we would want anyone to apply before quoting it.

  1. The gap to Copyleaks is not a ranking. We caught 580 of 600 AI-involved essays and Copyleaks caught 570. A paired test on that difference gives p = 0.15, inside the margin of error, so the honest statement is that the two tools are level overall. The one difference that does hold up is the weakest category: we never fell below 92.0% in any of the four, Copyleaks never fell below 86.7%, and every other tool in the run drops to 51.3% or lower somewhere. Copyleaks also caught more humanized text than we did, 93.3% against 92.0%.

  2. “Mixed” verdicts were counted as not-AI. That is how a teacher facing an ambiguous flag has to treat it, but it is a choice, and it is harsh on ZeroGPT, which returned “mixed” on 175 of the 600 AI texts. Counting those as detections would lift ZeroGPT from 18.8% to 48.0%, Pangram from 67.5% to 73.2% and GPTZero from 43.7% to 46.3%. Both readings are published.

  3. Zero false positives on 150 human essays does not mean zero false positives. All eight tools scored 0 of 150, and a control set of that size only bounds the true rate to about 2.5%. Evan’s earlier reviews in this forum found individual human texts flagged by Originality (a Wikipedia article at 99% AI) and Copyleaks (a 2003 BBC piece at 100%). Per-text errors exist at any accuracy level, ours included.

  4. One genre, one language, one snapshot. The corpus is 750 student essays from GEDE (Gehring and Paassen, Bielefeld University), about 288 words each, mostly by non-native writers, submitted once each in August 2026 at default settings, with Originality on its Lite model only. A benchmark on fiction, marketing copy or Spanish would be a different benchmark.

  5. Length. Under 200 words every tool weakens; we caught 91.7% there, Copyleaks 83.3%, Originality Lite 45.8%. Short text is where any verdict, including ours, deserves the least confidence.

  6. Two detectors people ask about are not in the table: Grammarly’s and Undetectable AI’s. They are on the list for the next run, and the rows will be published whichever way they go.

Humanized AI essays caught (of 150)
Copyleaks 93.3%
Clever AI Detector 92.0%
GPTZero 73.3%
Pangram 64.0%
Originality.ai Lite 51.3%
Winston AI 44.7%
QuillBot 22.0%
ZeroGPT 0.7%

On Gerda’s own small test: thank you, and it is worth saying plainly that a handful of texts is an impression, not a measurement. That is true of our competitors’ landing-page claims and it is true of our own anecdotes.

What this means for anyone using the tool: Clever AI Detector returns a 0 to 100 probability with sentence-level signals, not a verdict, and it is free with no account, up to 10,000 words per check and unlimited runs. The output is meant to be read, questioned and, where a person’s work is at stake, argued with. No detector score, including a 96.7% recall figure, is evidence of who wrote a text.

Recommendation: use it, and use it as one input. If you want the full table, the methodology and the alternative figures, they are on the benchmark page, and we would rather be quoted with the caveats than without them.